Gemini vs OpenAI API for SaaS Builders: An Honest Cost and Quality Comparison
Gemini vs OpenAI API pricing, tier by tier, in November 2026: worked monthly costs, caching and long-context differences, and the two Google price increases landing on 1 December and 1 January.
When I first wrote this post in July, the answer was simple: Gemini Flash was much cheaper than anything OpenAI sold at the same level, so for high-volume work it was the obvious first test. That's not true anymore. OpenAI cut prices in July and again when GPT-6 launched in September, and Google has scheduled two increases: Gemini 4 Argon and Carbon on 1 December, and the Gemini Flash models on 1 January.
So this is a rewrite. Same question, current numbers, and a straight answer for each price tier.
This post is part of the "Choose" section of the complete guide to LLM cost optimization. Every rate below comes from each provider's published schedule, checked on 17 Nov 2026.
The rates, side by side
Grouped roughly by price, which is not the same as grouping by quality.
| Tier | OpenAI | Input / output per 1M | Input / output per 1M | |
|---|---|---|---|---|
| Budget | GPT-6 Luna | $0.10 / $0.50 | Gemini 3.1 Flash-Lite | $0.25 / $1.50 |
| Mid | GPT-6.1 Terra | $1.00 / $5.00 | Gemini 3.8 Flash | $0.75 / $3.75, then $1.50 / $7.50 from 1 Jan |
| Mid | Gemini 4 Hydrogen | $1.50 / $7.50 | ||
| Upper | GPT-6.1 Sol | $2.00 / $10.00 | Gemini 3.1 Pro | $2.00 / $12.00 |
| Upper | Gemini 4 Argon | $2.00 / $10.00, then $4.00 / $20.00 from 1 Dec | ||
| Top | GPT-6 Astra | $10.00 / $50.00 | Gemini 4 Carbon | $2.00 / $10.00, then $4.00 / $20.00 from 1 Dec |
Two things to notice before any arithmetic. Google's model names don't map neatly onto OpenAI's, so "which Gemini competes with which GPT" is a judgment call. Run your own quality test. And half of Google's current prices are introductory, with an end date already published.
What one feature costs on each
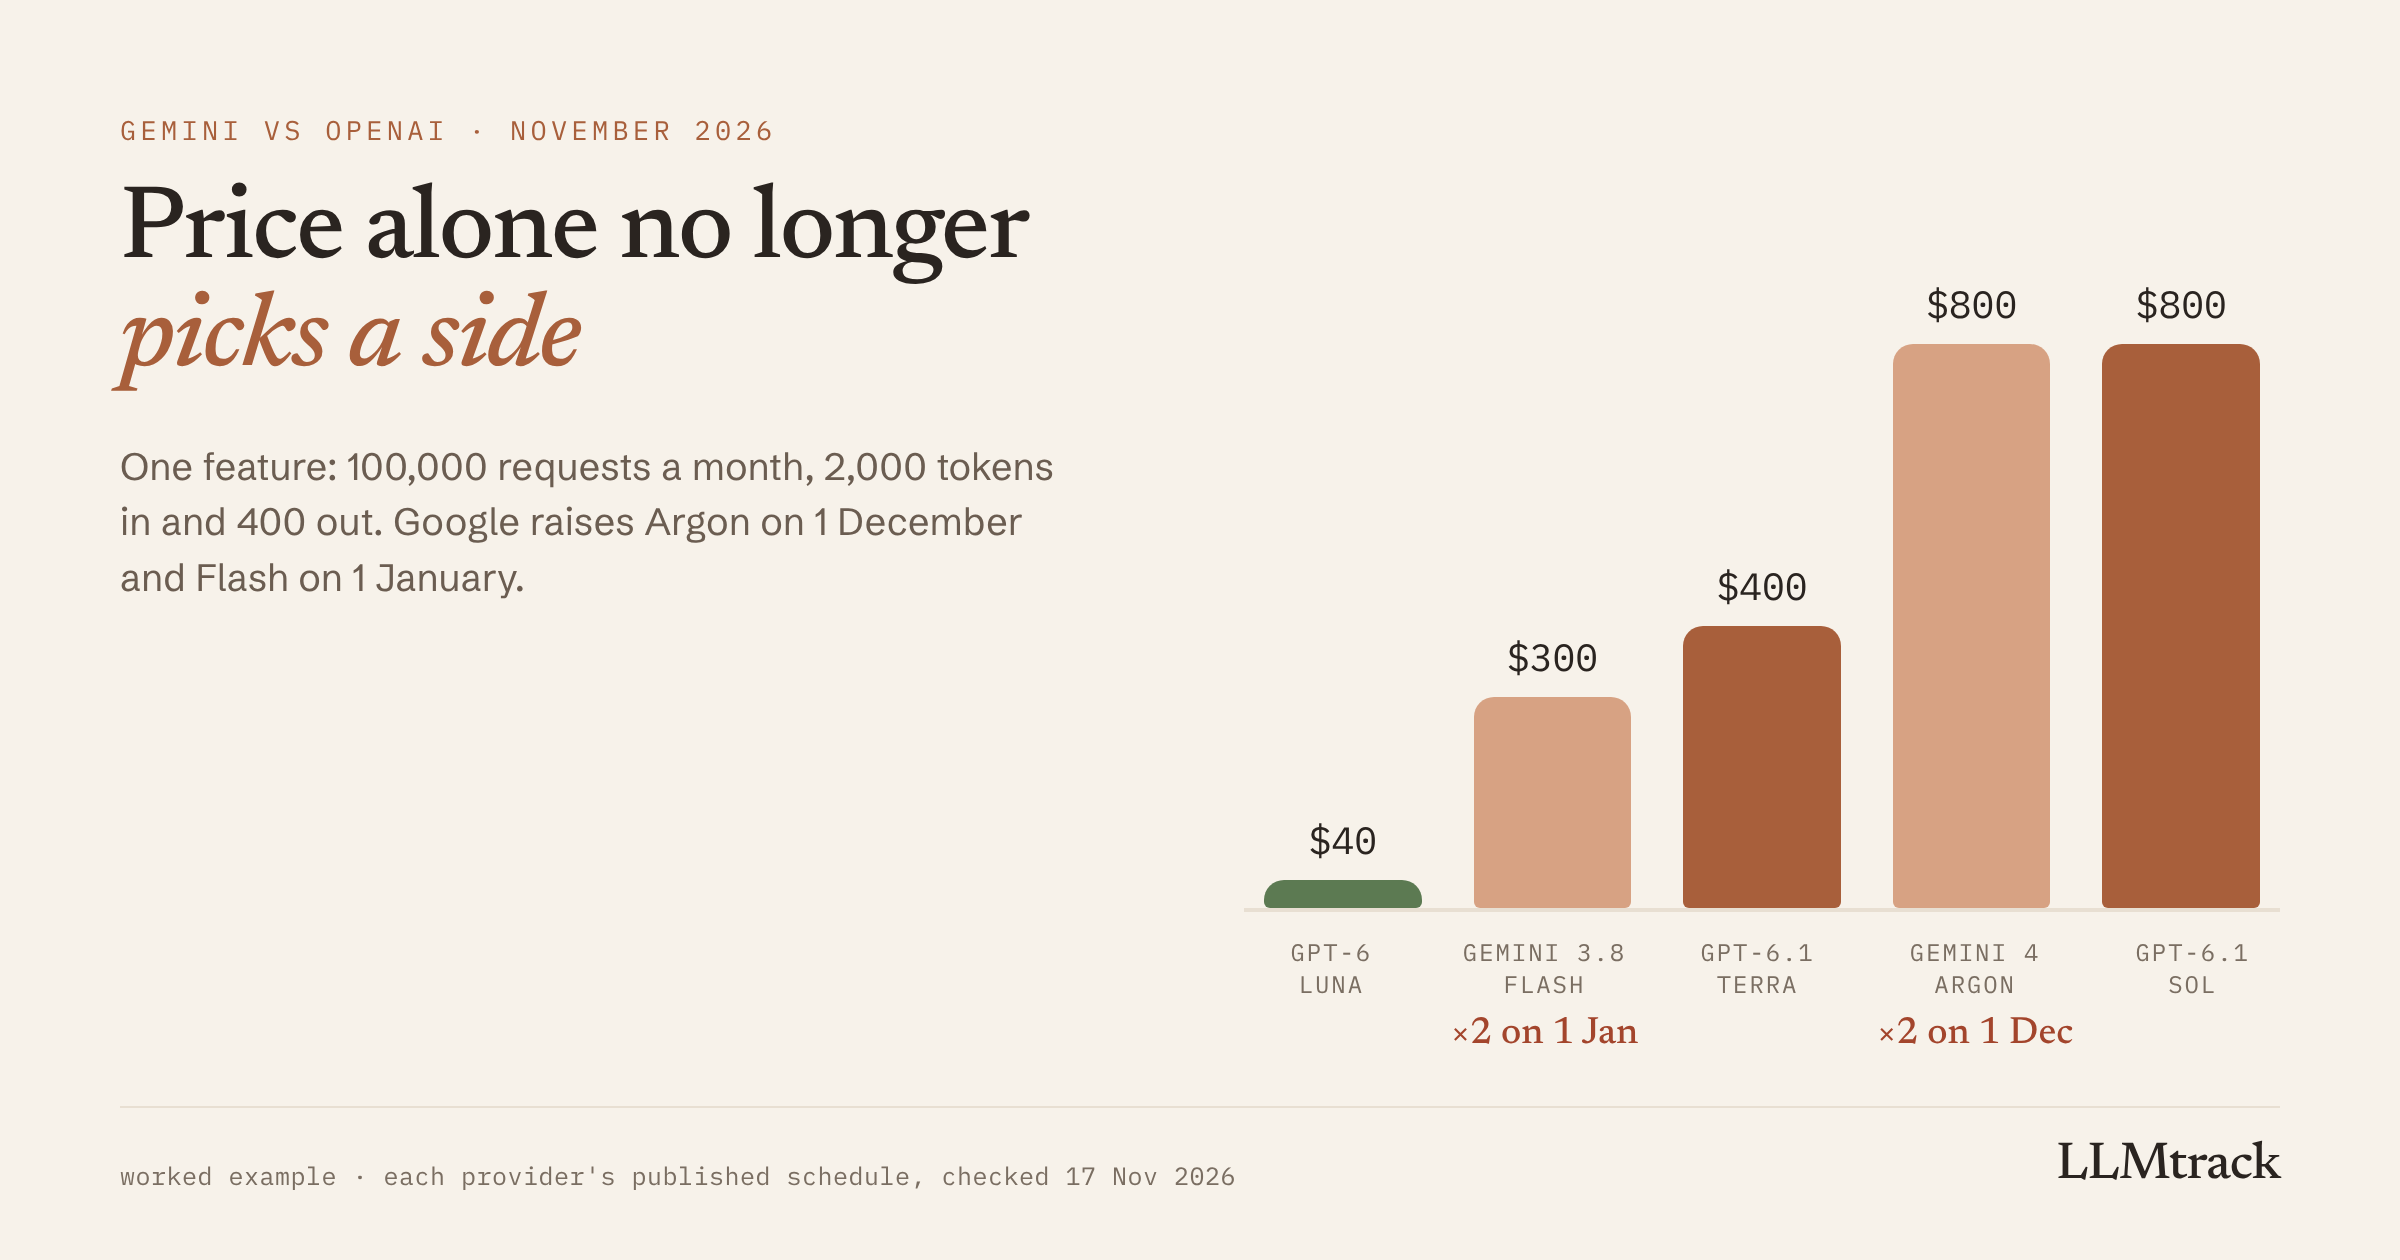
Take a typical SaaS feature: 100,000 requests a month, each with 2,000 input tokens (instructions, some context, the user's text) and 400 output tokens. That's 200 million input and 40 million output tokens.
| Model | Per month now | After the scheduled increases |
|---|---|---|
| GPT-6 Luna | $40 | $40 |
| Gemini 3.1 Flash-Lite | $110 | $110 |
| Gemini 3.8 Flash | $300 | $600 from 1 Jan |
| GPT-6.1 Terra | $400 | $400 |
| Gemini 4 Hydrogen | $600 | $600 |
| GPT-6.1 Sol | $800 | $800 |
| Gemini 4 Argon | $800 | $1,600 from 1 Dec |
| Gemini 3.1 Pro | $880 | $880 |
| GPT-6 Astra | $4,000 | $4,000 |
At this request shape, output is about half the bill on every model, because output rates are 5x to 6x input. A feature that writes long answers shifts the comparison toward whichever model has the cheaper output rate. One that reads long documents and returns a label shifts it toward cheap input.
Where the two providers bill differently
Caching. Both discount repeated prompt prefixes heavily. Gemini's implicit caching has no write fee, and Gemini 4's cached input is 95% off. OpenAI's cached reads are 90% off (95% on GPT-6.1 Sol and Terra), but on GPT-5.6 and later, writing to the cache costs 1.25x input. For a feature with a big, stable system prompt and steady traffic, the difference is small. For bursty traffic where the cache keeps expiring, Gemini's no-write-fee model is cheaper. More in how prompt caching works.
Long context. Both charge more for very long prompts. Gemini 3.1 Pro goes from $2 to $4 per million input tokens above 200,000 tokens. OpenAI's GPT-6 models switch to higher rates above 272,000 tokens (GPT-6.1 Sol goes from $2 to $4 input). If a feature regularly sends whole documents, check where its prompts sit relative to those lines.
Thinking. Both bill reasoning as output. Google states it plainly: output prices include thinking tokens. OpenAI reports reasoning tokens separately in the usage object, but they bill at the output rate too. A reasoning-heavy model can write several times more tokens than its visible answer, which is why reasoning tokens deserve their own look.
Discount tiers. Both sell Batch and Flex at half price for requests that can wait, and both sell a pricier priority tier. Batch and Flex discounts covers when that's worth it.
Is switching worth it?
Switching providers costs engineering time, and the saving depends on the tier. Three cases where I'd test it:
- You're on GPT-4o Mini or another old budget model. GPT-6 Luna is cheaper than Mini and cheaper than any Gemini model right now, and GPT-4o Mini leaves the OpenAI API on 14 January 2027 anyway. This is a model change inside OpenAI, not a provider switch.
- You're on GPT-6.1 Terra for a high-volume mid-tier feature. Gemini 3.8 Flash is 25% cheaper until 31 December. After 1 January it's 50% more expensive on this request shape. Don't migrate for a price that ends in six weeks.
- You use a long-context or document-heavy feature. Both have long-context premiums at different thresholds. Run the numbers on your actual prompt sizes.
Testing is cheaper than it used to be. Google publishes an OpenAI-compatible endpoint for the Gemini API, so a first test can be a base URL and model name change in the OpenAI SDK you already use. Run it on a slice of one feature's traffic, keep the old model on the rest, and compare cost per request and your quality check for a week.
Measure both on the same feature
The reason to track cost per feature is exactly this kind of decision. A blended monthly total can't tell you whether moving one feature to Gemini saved money or whether a traffic change hid an increase. With LLMtrack, both providers go through the same call after the response, labeled with the same feature:
import { LLMtrack, fromOpenAIUsage } from 'llmtrack';
const llmtrack = new LLMtrack({
apiKey: process.env.LLMTRACK_API_KEY,
onError: (err) => console.error('llmtrack', err),
});
// Same feature label for both arms of the test
llmtrack.track({
provider: 'google',
model: 'gemini-3.8-flash',
feature: 'support-reply',
...fromOpenAIUsage(response.usage), // the OpenAI-compatible endpoint returns OpenAI-style usage
});LLMtrack prices each request from each provider's published schedule, including the scheduled Google increases once they take effect, so the comparison stays honest across the price change. Model Intelligence then tells you per feature whether a cheaper model is worth testing, and says "keep" when it isn't. You can start on the free plan, or estimate a feature first with the LLM cost calculator.
FAQ
It depends on the tier. At the budget end, OpenAI's GPT-6 Luna ($0.10 input, $0.50 output per million tokens) is cheaper than every current Gemini model. In the middle, Gemini 3.8 Flash ($0.75, $3.75) is cheaper than GPT-6.1 Terra ($1, $5) until 31 December 2026, when Flash doubles. At the top, Gemini 4 Argon and Carbon match GPT-6.1 Sol at $2 and $10 until 30 November, then rise to $4 and $20.
On 1 January 2027. Gemini 3.8 Flash, 3.7 Flash and 3.6 Flash go from $0.75 to $1.50 per million input tokens and from $3.75 to $7.50 per million output tokens. Cached input goes from $0.075 to $0.15.
$2 per million input tokens and $10 per million output tokens through 30 November 2026, then $4 and $20 from 1 December. Gemini 4 Carbon has the same rates and the same change. Gemini 4 Hydrogen costs $1.50 and $7.50.
Yes. Google publishes an OpenAI-compatible endpoint for the Gemini API, so you can point the OpenAI SDK at Google's base URL with a Gemini API key and model name. Not every OpenAI feature is supported, so test the parts your feature uses.
They're billed at the output rate. Google's pricing for its current models states that output prices include thinking tokens, so a request that thinks a lot costs more than its visible answer suggests.
Sources
Checked on 17 Nov 2026:
Compare Gemini and OpenAI on your own traffic
Free plan, every feature, no card.
Start tracking free →