The Cheapest LLM APIs, Compared (And Why the Ranking Flips)
The cheapest LLM APIs in November 2026, from open-weight models at $0.05 per million tokens to the flagships, and two worked workloads that show why the cheapest model for one feature is the wrong one for another.
"Which LLM API is cheapest?" has no single answer, and the reason is structural. Providers charge different rates for input and output, add surcharges for long prompts, and layer caching and batch discounts on top. A model that wins on a short classification task can lose badly on a long writing task.
This is a snapshot of current rates and, more usefully, a way to read them. I first published it in August; the market has moved enough since then that almost every row changed.
This post is part of the "Choose" section of the complete guide to LLM cost optimization. Rates are from each provider's published schedule, checked on 17 Nov 2026. For today's numbers, the LLM API pricing sheet is re-synced daily.
The current landscape
USD per million tokens, input / output, standard tier:
| Tier | Model | Input | Output | Notes |
|---|---|---|---|---|
| Floor | gpt-oss-20b (Together AI) | $0.05 | $0.20 | Open-weight; $0.075 / $0.30 on Groq |
| Floor | Ministral 3B (Mistral) | $0.10 | $0.10 | Same rate in and out |
| Floor | GPT-6 Luna (OpenAI) | $0.10 | $0.50 | $0.20 / $0.75 above 272K tokens |
| Floor | Claude Haiku 5.5 (Anthropic) | $0.10 | $0.50 | $0.50 / $2.50 above 100K tokens |
| Floor | DeepSeek Flash | $0.15 | $0.60 | Very cheap cache reads |
| Floor | Mistral Small | $0.15 | $0.60 | |
| Floor | Gemini 3.1 Flash-Lite | $0.25 | $1.50 | |
| Mid | DeepSeek V4 Pro | $0.66 | $1.98 | |
| Mid | Mistral Large 4 | $0.70 | $2.10 | |
| Mid | Gemini 3.8 Flash | $0.75 | $3.75 | Doubles to $1.50 / $7.50 on 1 Jan 2027 |
| Mid | GPT-6.1 Terra | $1.00 | $5.00 | |
| Mid | Grok 4.3 (xAI) | $1.25 | $2.50 | Low output rate |
| Mid | Gemini 4 Hydrogen | $1.50 | $7.50 | |
| Upper | Grok 4.7 (xAI) | $2.00 | $6.00 | |
| Upper | GPT-6.1 Sol | $2.00 | $10.00 | |
| Upper | Claude Sonnet 5.5 | $2.00 | $10.00 | |
| Upper | Gemini 3.1 Pro | $2.00 | $12.00 | $4 / $18 above 200K tokens |
| Flagship | Claude Opus 5.5 | $4.00 | $20.00 | |
| Flagship | Claude Fable 5.2 | $8.00 | $40.00 | |
| Flagship | GPT-6 Astra | $10.00 | $50.00 |
Output prices differ by more than 100x between the floor and the flagships. Picking the right tier for each task matters far more than finding a slightly better rate on any one model.
Two older names are missing on purpose. GPT-4o Mini, the default cheap model for a lot of apps, leaves OpenAI's API on 14 January 2027, and GPT-6 Luna, its named replacement, is cheaper on both input and output. Gemini 3.5 Flash-Lite ($0.30 / $2.50) is still available but costs more than 3.1 Flash-Lite.
Why the ranking flips
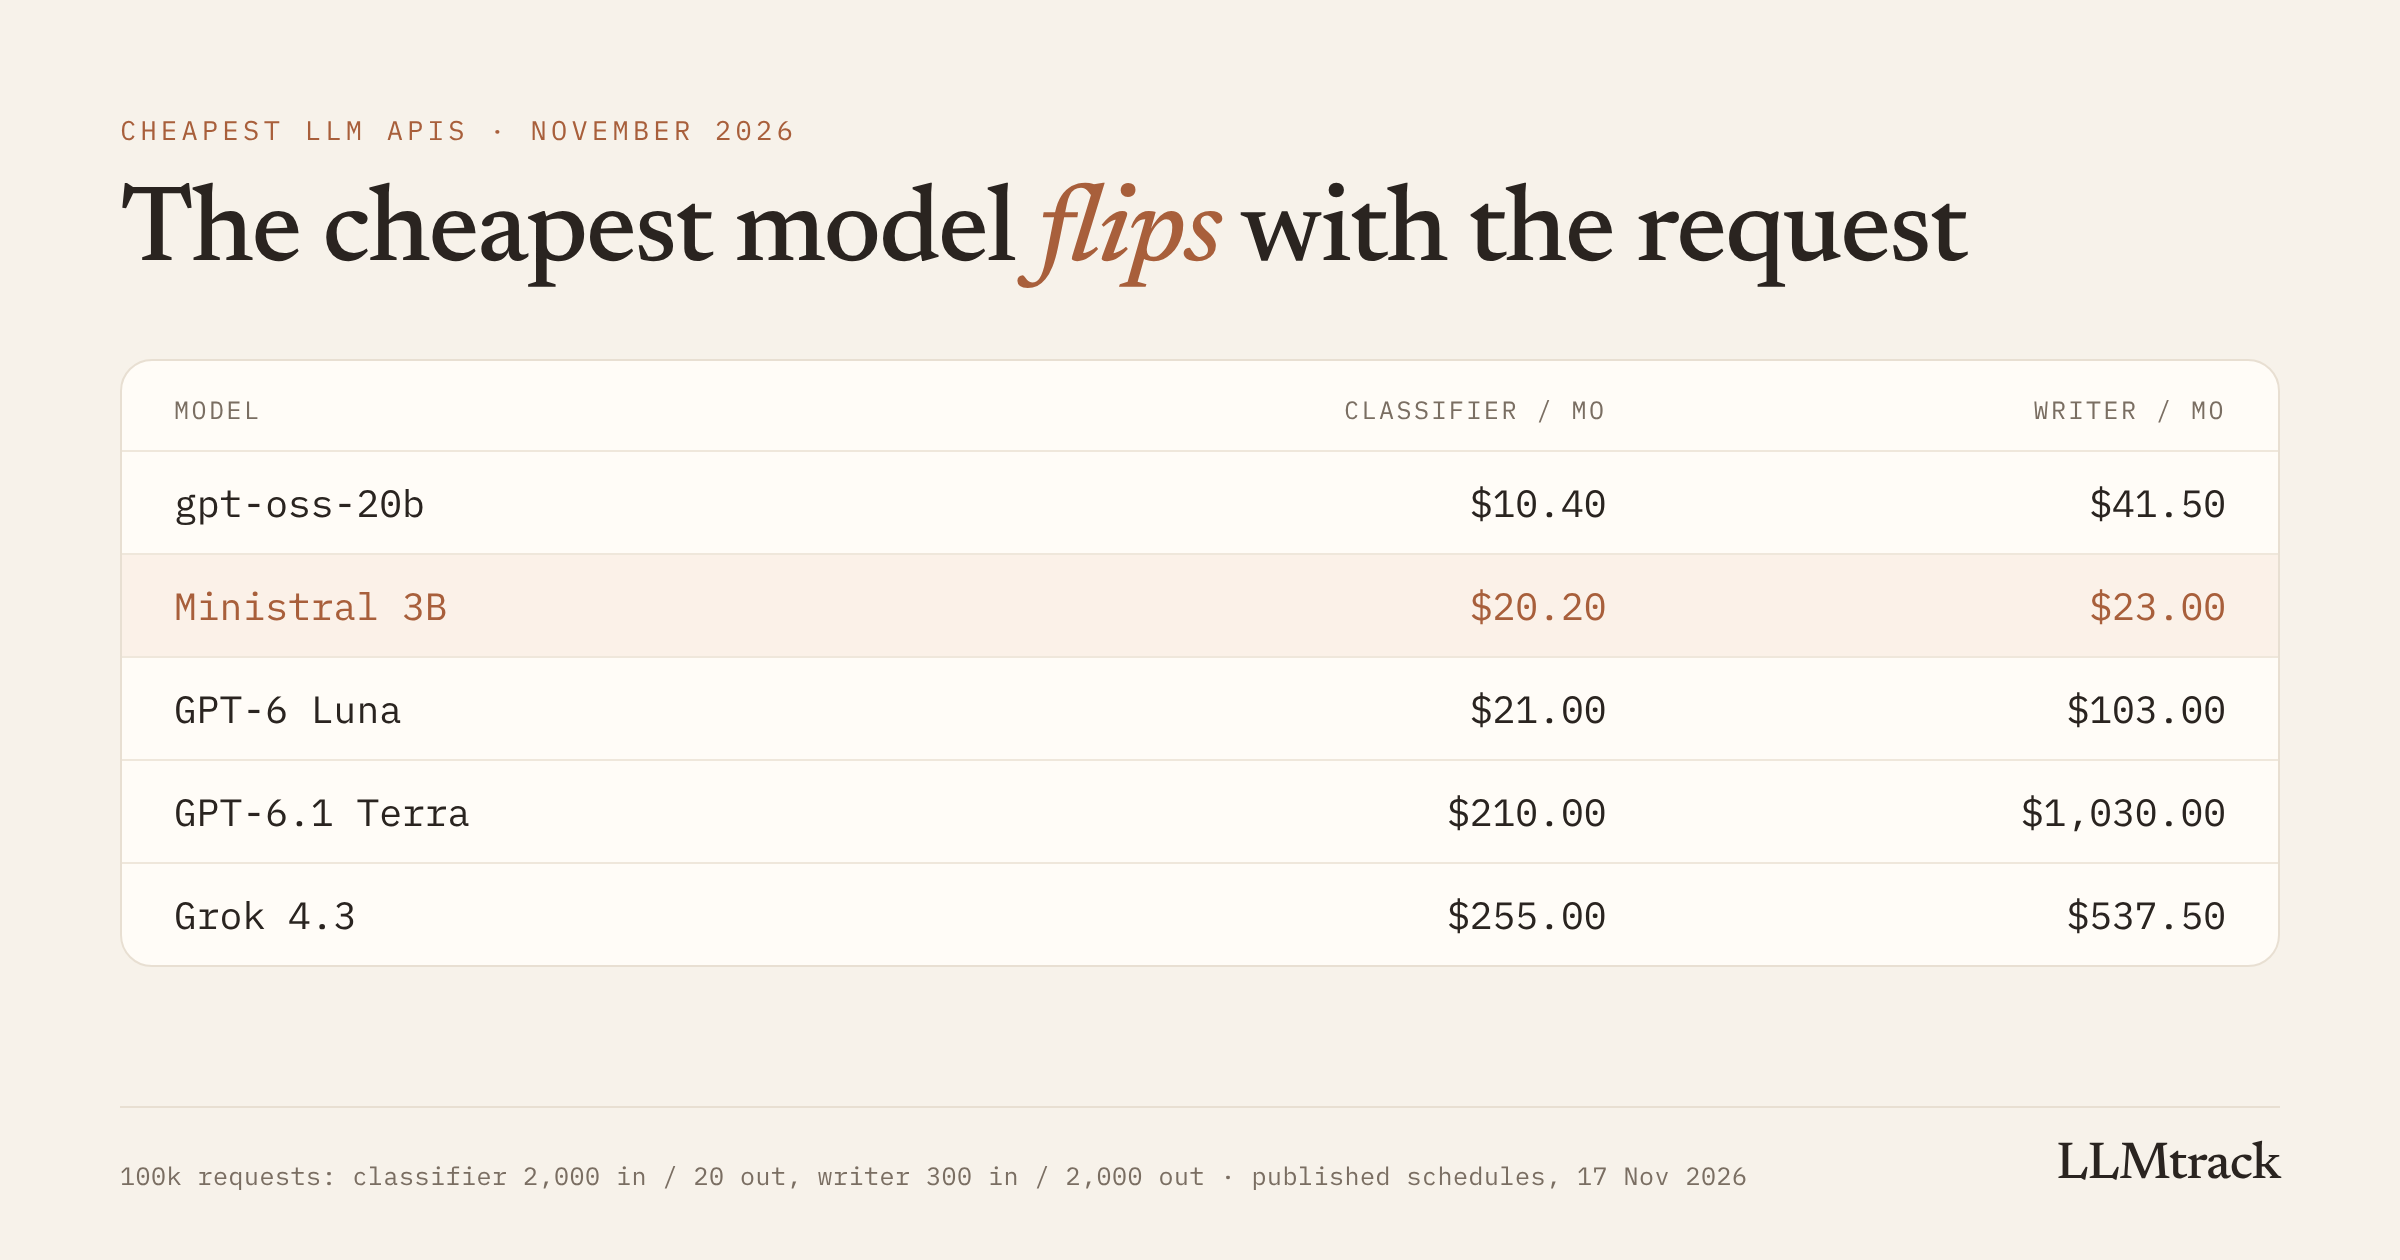
Take two features, each at 100,000 requests a month:
- A classifier: 2,000 input tokens (instructions plus the item), 20 output tokens. 200 million input, 2 million output.
- A writer: 300 input tokens (a short brief), 2,000 output tokens. 30 million input, 200 million output.
| Model | Classifier, per month | Writer, per month |
|---|---|---|
| gpt-oss-20b (Together AI) | $10.40 | $41.50 |
| Ministral 3B | $20.20 | $23.00 |
| GPT-6 Luna | $21.00 | $103.00 |
| DeepSeek Flash | $31.20 | $124.50 |
| Gemini 3.1 Flash-Lite | $53.00 | $307.50 |
| DeepSeek V4 Pro | $135.96 | $415.80 |
| Mistral Large 4 | $144.20 | $441.00 |
| GPT-6.1 Terra | $210.00 | $1,030.00 |
| Grok 4.3 | $255.00 | $537.50 |
Three flips in that table:
- Ministral 3B and GPT-6 Luna cost about the same on the classifier. On the writer, Ministral is less than a quarter of Luna, because its output costs the same as its input.
- Grok 4.3 costs 21% more than GPT-6.1 Terra on the classifier, and about half as much on the writer. Grok's input is pricier, its output much cheaper.
- gpt-oss-20b is the cheapest classifier, but not the cheapest writer. Ministral 3B beats it once output dominates.
None of this says which model is good enough for the job. It says the price ranking you read off a table only holds for the request shape you had in mind when you read it.
Four things the headline rate hides
Output costs more than input, by different amounts. On most models output is 3x to 6x input. On a few it's 1x or 2x. That ratio, not the input price, decides the cost of anything that writes.
Long prompts can change the rate. Claude Haiku 5.5 charges five times its normal rates once a prompt passes 100,000 tokens. Gemini 3.1 Pro roughly doubles above 200,000, and OpenAI's GPT-6 models step up above 272,000. Sonnet 5.5 and Opus 5.5 charge a flat rate across their full context. On short prompts this doesn't matter; on document-heavy features it can reverse a comparison.
Caching and batch stack on top. A cached prefix bills at about a tenth of input on the big three, sometimes less, and Batch or Flex halves everything. A mid-priced model with good caching can undercut a cheaper one without it. How prompt caching works and Batch and Flex discounts cover both.
Tokenizers differ. The same text doesn't produce the same number of tokens on every model. Two models with the same rate can bill differently for the same prompt. Count tokens on a sample of your real prompts before trusting a comparison.
How to actually pick
Match the tier to the task instead of hunting for one cheapest model:
- High-volume, simple work like classification, routing, extraction and short summaries belongs on the floor tier. Test two or three floor models on real inputs; quality varies more than price does here.
- Production features where accuracy, context or tool use matter usually land in the mid or upper tier. Your input/output ratio and prompt length decide which one is cheapest.
- Hard reasoning is the minority of requests that genuinely need a flagship. The mistake that inflates most bills is sending everything to a flagship because some of it needs one. Defaulting every feature to a flagship model covers that pattern.
Before moving a feature, check what the cheaper model is worse at on a slice of real traffic.
The number that decides it is your own
Every ranking here uses list prices and request shapes I made up. The cheapest model for your app depends on its real input/output split, prompt sizes, cache hit rate and tokenizer, none of which are on a pricing page.
LLMtrack works that out from your own traffic. It records token counts per feature as requests happen, and Model Intelligence projects what each feature would cost on cheaper models using your real averages, then says "switch", "test first" or "keep" depending on whether the quality trade looks worth it. You can start on the free plan, or try a request shape across models in the LLM cost calculator.
FAQ
For capable hosted models, the floor in November 2026 is around $0.05 to $0.15 per million input tokens: gpt-oss-20b on Together AI ($0.05 / $0.20), Ministral 3B ($0.10 / $0.10), GPT-6 Luna and Claude Haiku 5.5 ($0.10 / $0.50), and DeepSeek Flash and Mistral Small ($0.15 / $0.60). Which is cheapest for you depends on how much your feature writes.
GPT-6 Luna, at $0.10 per million input tokens and $0.50 per million output tokens, or half that on Batch and Flex.
Claude Haiku 5.5, at $0.10 per million input tokens and $0.50 per million output tokens for prompts up to 100,000 tokens. Above that, the whole request pays $0.50 and $2.50.
Because input and output are priced differently, and the gap differs by model. A feature that reads a lot and writes little is priced off the input rate; one that writes a lot is priced off the output rate. A model can be cheapest for one and expensive for the other.
No. GPT-6 Luna costs less on both input and output, and GPT-4o Mini leaves OpenAI's API on 14 January 2027.
Sources
Checked on 17 Nov 2026:
Find the cheapest model for your own traffic
Free plan, every feature, no card.
Start tracking free →