Reasoning Tokens: The Invisible Line Item in Every New AI Model
GPT-6, Claude 5.5 and Gemini 3.8 all think before they answer, and that thinking bills at the output rate. Here's what it costs on current models, where each provider reports it, and how to stop paying for reasoning that doesn't help.
For a while, choosing a model was one decision: GPT, Claude or Gemini, and the rate on the pricing page was roughly what you paid. The current generation broke that. The question now is which model, at what effort, and the second half often moves the bill more than the first.
The reason is the reasoning token. Current models from all three big providers work through a problem before they answer, and that working is billed as output, the most expensive token on the page. On a hard request a model can spend thousands of tokens thinking and a few hundred answering. You pay for all of it, and on some providers you never see the part you paid the most for.
This post is part of the "Understand" section of the complete guide to LLM cost optimization. I first wrote it in August; this version has current models, current rates and the exact usage fields to read.
What a reasoning token is
Before it writes the answer, a reasoning model generates a private chain of thought: working through the problem, checking itself, trying alternatives. Those intermediate tokens are called reasoning tokens (OpenAI's term) or thinking tokens (Anthropic's and Google's). The billing rule is the same everywhere: they're charged at the output rate. There's no cheaper meter for thinking.
What differs is how much you see and where the count lives:
| Provider | Where reasoning shows up in usage | Is it inside the output count? |
|---|---|---|
| OpenAI, Responses API | usage.output_tokens_details.reasoning_tokens | Yes, included in output_tokens |
| OpenAI, Chat Completions | usage.completion_tokens_details.reasoning_tokens | Yes, included in completion_tokens |
| Anthropic | No separate field; thinking is counted in output_tokens | Yes |
| Google Gemini | usageMetadata.thoughtsTokenCount | Google's pricing states output prices include thinking tokens |
That table is also the most common way people get the cost wrong. If you add OpenAI's reasoning count on top of the output count, or add an estimate of Claude's thinking to output_tokens, you charge the same tokens twice.
What it costs on current models
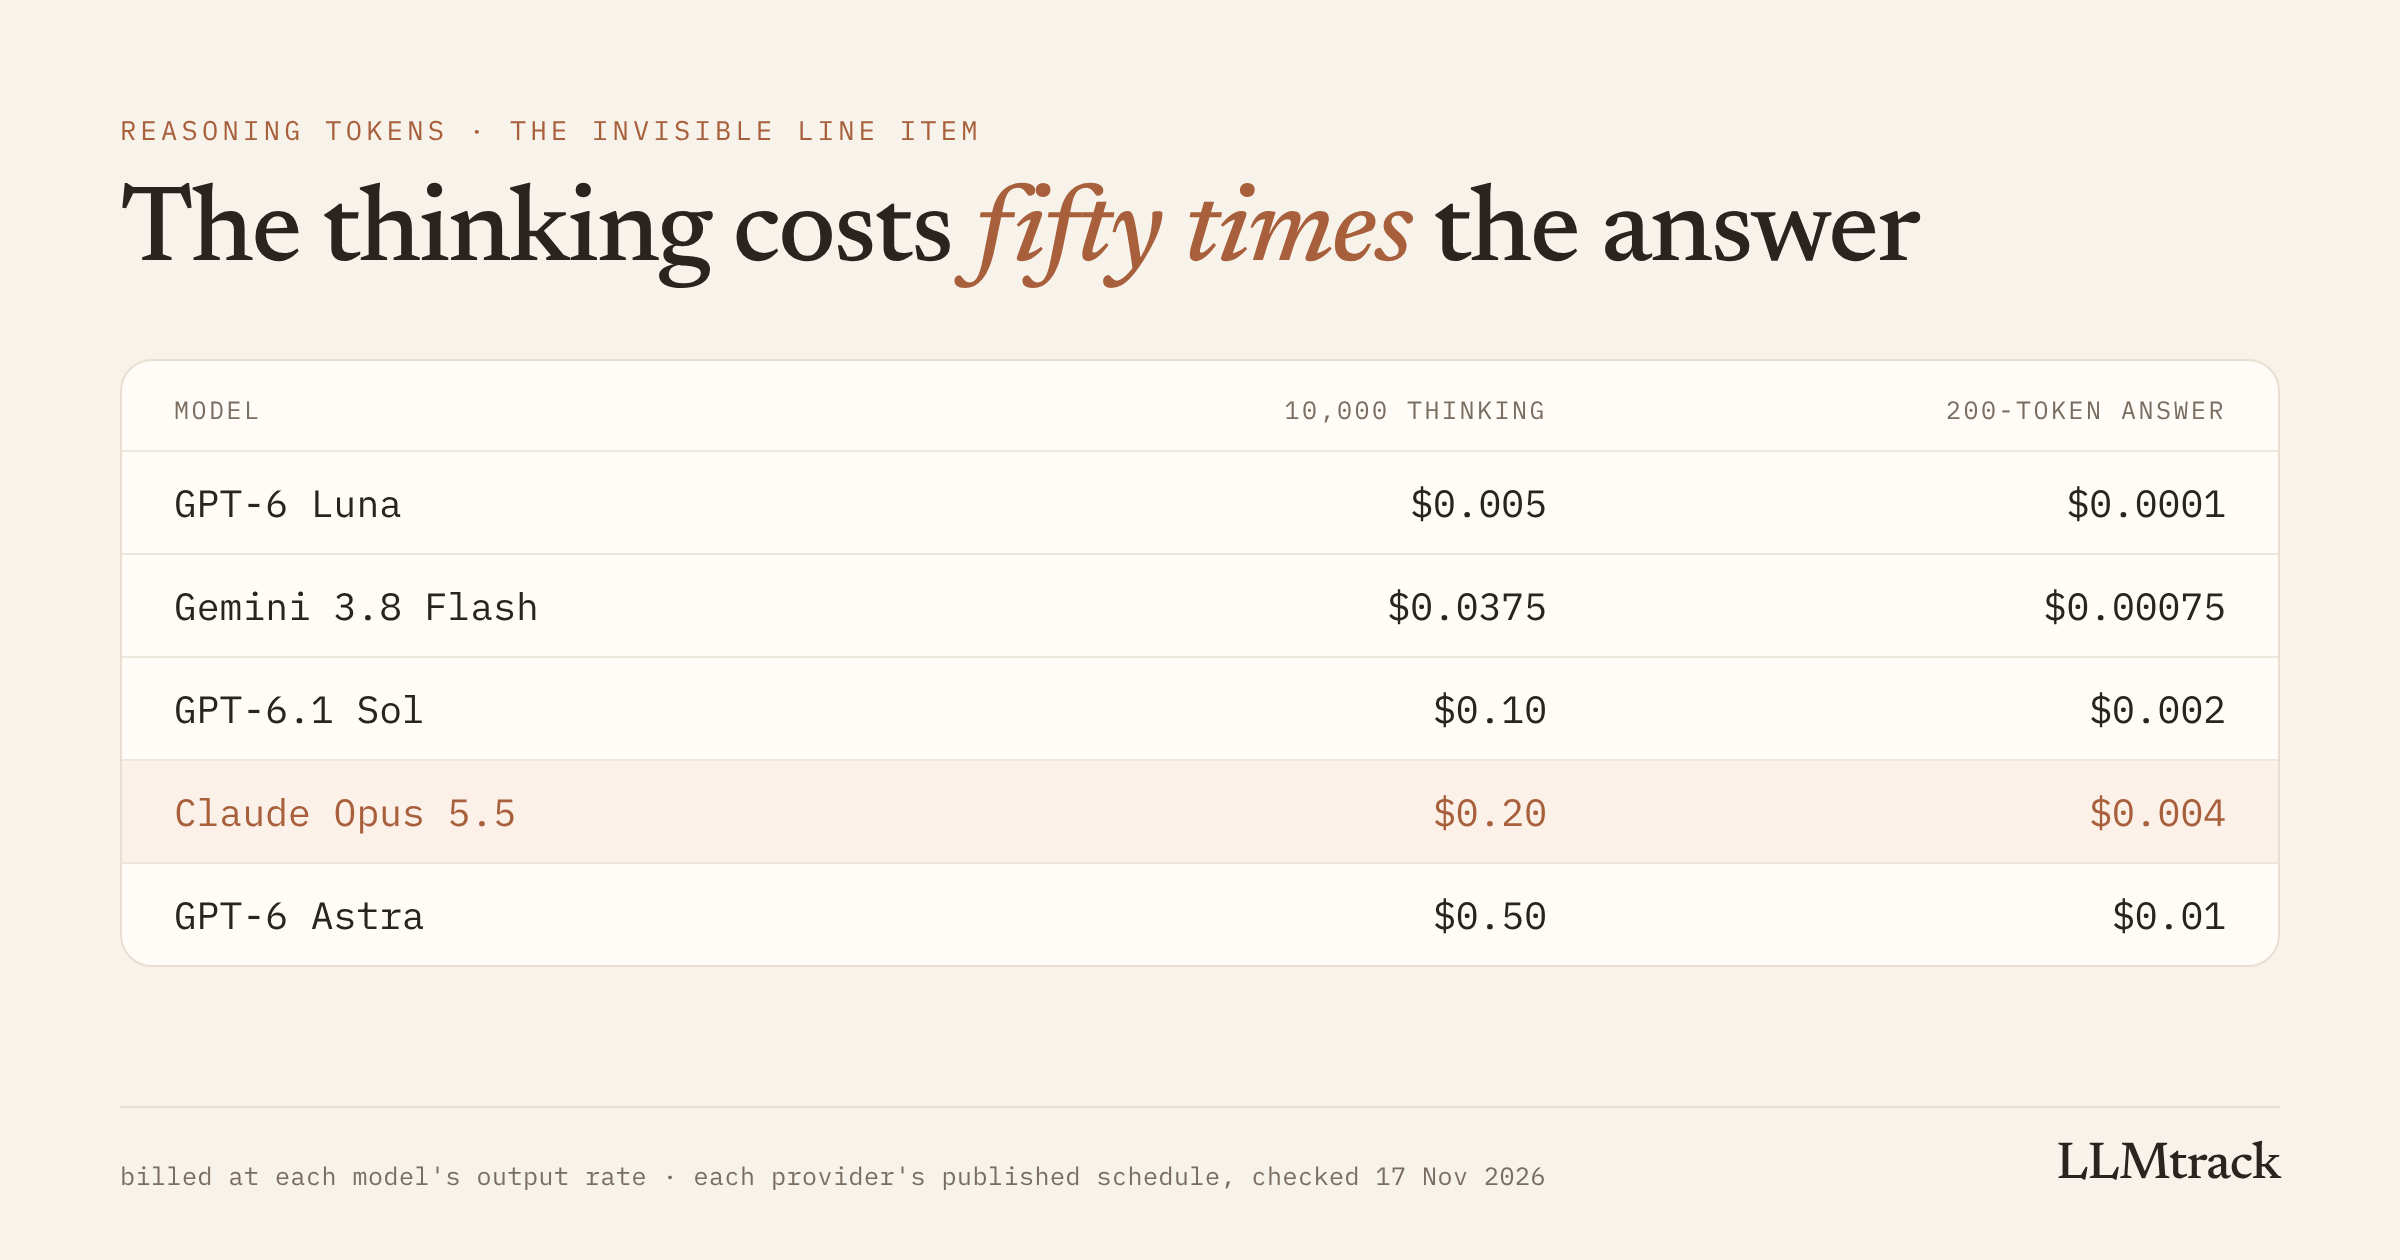
A request that thinks for 10,000 tokens and answers in 200, at each model's output rate on 17 Nov 2026:
| Model | Output rate per 1M | Thinking cost | Answer cost |
|---|---|---|---|
| GPT-6 Luna | $0.50 | $0.005 | $0.0001 |
| Claude Haiku 5.5 | $0.50 | $0.005 | $0.0001 |
| Gemini 3.8 Flash | $3.75 ($7.50 from 1 Jan) | $0.0375 | $0.00075 |
| GPT-6.1 Sol | $10 | $0.10 | $0.002 |
| Claude Sonnet 5.5 | $10 | $0.10 | $0.002 |
| Claude Opus 5.5 | $20 | $0.20 | $0.004 |
| GPT-6 Astra | $50 | $0.50 | $0.01 |
In every row the thinking costs fifty times the answer, because it's fifty times the tokens at the same rate. On a feature that handles 20,000 requests a day on GPT-6.1 Sol, that thinking is $2,000 a day, and nothing in the response your code receives looks unusual.
Every model now ships with a dial
Reasoning depth became a setting rather than a model choice. Each provider exposes it differently, and the names change between model generations, so check the current docs for the model you use:
- OpenAI uses a reasoning effort parameter on the GPT-6 and GPT-5.6 models. Effort works as a ceiling more than a target: on a prompt the model judges easy, it may reason very little even at high effort.
- Anthropic uses an effort setting on the Claude 5 and 5.5 models, with thinking on by default on current models.
- Google uses thinking levels on Gemini 3.x and 4 models, with a separate mode for the hardest problems.
The practical result is that two teams on the same model can pay very different amounts for the same feature, depending on a parameter one of them never changed from the default.
More thinking isn't always better
Reasoning pays off on hard problems: multi-step logic, long agent chains, complex code. On a lot of everyday product work it buys little. Classification, extraction, reformatting, routing a ticket to a queue, pulling a date out of an email: the answer is usually the same at low effort as at high, and every extra reasoning token is spent for nothing.
That makes effort one of the cheapest levers available. The test is simple and doesn't need a research budget:
- Pick one feature that does a well-defined task.
- Run 200 real requests at its current effort and at the lowest effort the model allows.
- Compare the answers with whatever check you already trust: exact match on labels, schema validation, a quick read of 30 at random.
- Compare output tokens per request between the two runs.
If the answers match and output tokens drop by half, that's half the feature's output cost gone. If quality drops, you've learned the feature genuinely needs the thinking, which is worth knowing too. How to check quality before switching to a cheaper model covers the same kind of test for model changes.
Things that quietly raise reasoning spend
- A model upgrade with a higher default. Moving to a newer model can change the default effort. Same prompt, same traffic, more output tokens.
- Agents. Each step in an agent loop can think. Ten steps of moderate thinking add up faster than one hard answer. How one bad agent loop runs up a bill shows the pattern.
- Retries on timeouts. Long thinking makes requests slower, which makes timeouts more likely, which means paying for the thinking twice.
- Long outputs requested for short answers. A generous
max_tokensgives the model room to think more than it needs to.
You can't tune a dial you can't see
A provider dashboard shows output tokens by model and day. It doesn't say which feature did the thinking, or whether a given effort setting is earning its cost. The reasoning count is in every response, though, so the fix is to record it per request, next to the feature and the model.
LLMtrack does that from the usage object. Its SDK adapters read OpenAI's reasoning count and price it at the output rate without adding it twice, and leave Anthropic's thinking inside output_tokens where it already is:
llmtrack.track({
provider: 'openai',
model: response.model,
feature: 'contract-review',
metadata: { effort: 'medium' },
...fromOpenAIUsage(response.usage),
});Putting the effort level in metadata lets you compare cost per request for the same feature before and after you change it. You can start on the free plan, or estimate the effect of reasoning on a feature with the LLM cost calculator.
FAQ
Yes, at the model's output rate. OpenAI, Anthropic and Google all charge for reasoning or thinking tokens as output, even though most of them never appear in the reply.
In the usage object of each response: output_tokens_details.reasoning_tokens in the Responses API, or completion_tokens_details.reasoning_tokens in Chat Completions. They're already included in the total output count, so don't add them again.
No. Anthropic includes thinking tokens in output_tokens. Adding a separate thinking estimate on top double-counts them.
Lower the reasoning effort on features where more thinking doesn't change the answer, such as classification, extraction and routing. Test it on a few hundred real requests first, compare the answers and output tokens per request, and keep higher effort only where quality actually needs it.
They're billed at the output rate. Google's pricing for its current models states that output prices include thinking tokens, and the count is reported as thoughtsTokenCount in the usage metadata.
Sources
Checked on 17 Nov 2026:
See which features pay for thinking
Free plan, every feature, no card.
Start tracking free →