Prompt Caching: The 90% Discount Most LLM Apps Aren't Using
OpenAI, Anthropic and Google all bill a repeated prompt prefix at about a tenth of the normal input rate. Here's how each one charges for caching in November 2026, what it saves on a real workload, and where it quietly costs more.
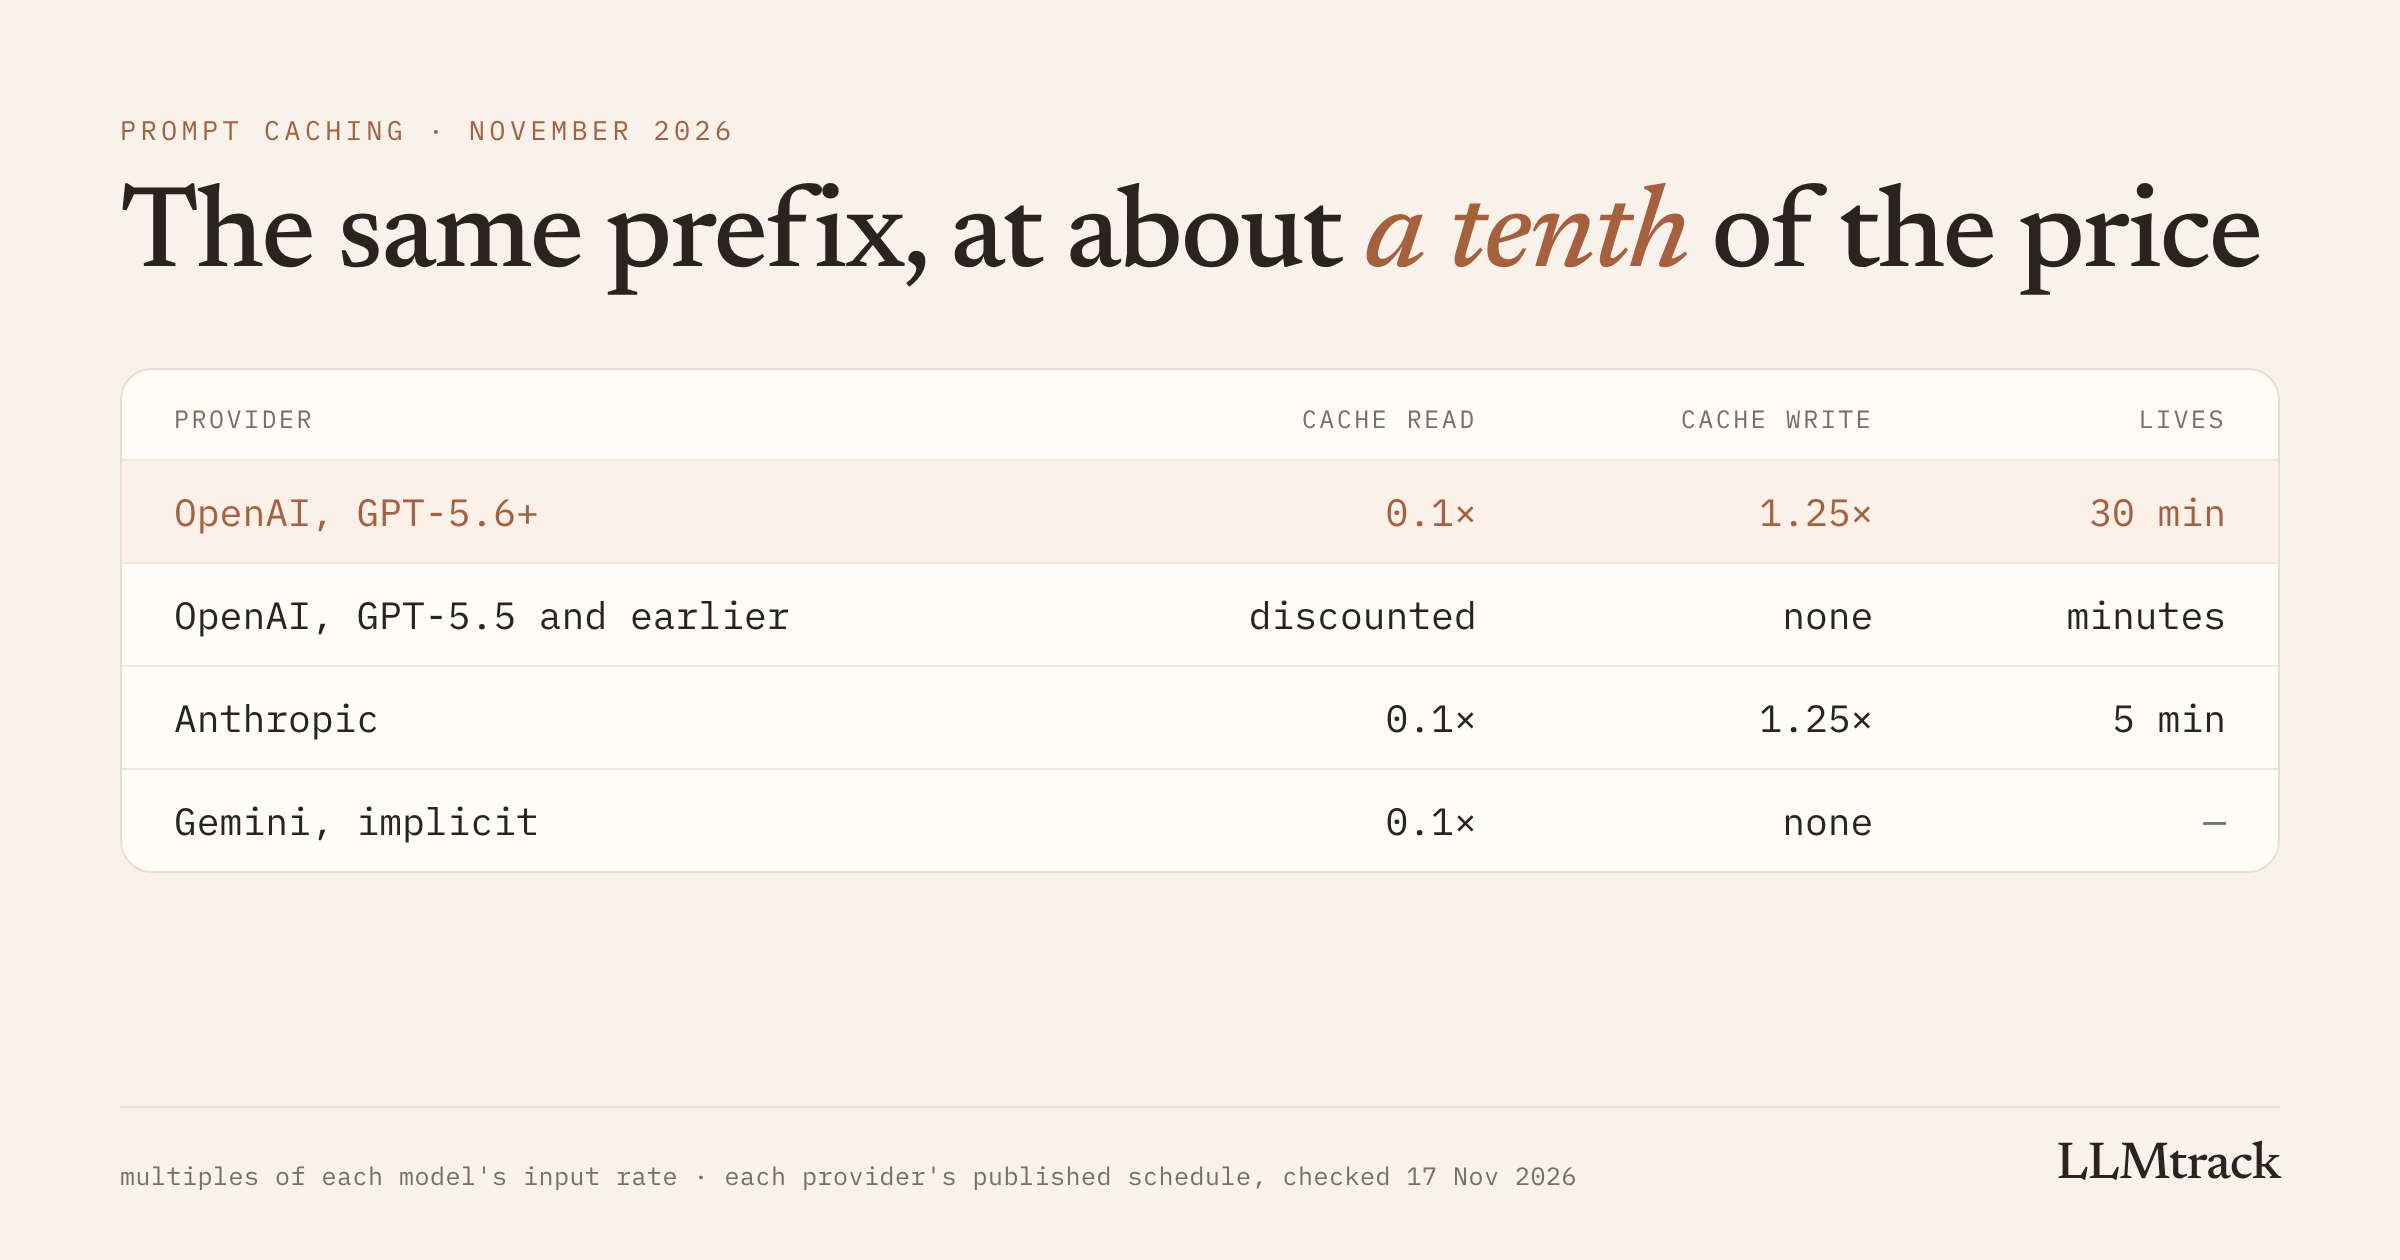
Most production LLM apps send the same block of text at the start of every request. A system prompt with rules, a few examples, tool definitions, maybe a document the model needs every time. That prefix is usually the biggest part of the prompt, and it doesn't change from one call to the next.
Prompt caching is how providers stop charging full price for that repetition. When it works, the repeated part of the prompt bills at roughly a tenth of the normal input rate. On a feature whose prompts are mostly fixed context, that's close to a 90% cut in input cost, with no change to the model or the answers.
This post is part of the "Reduce" section of the complete guide to LLM cost optimization. I first wrote it in August. This version has the current rates, including OpenAI's new cache-write fee, which changed the advice for anyone on GPT-5.6 or later.
What caching actually does
A model reads a prompt as an ordered list of tokens. Providers cache from the front: they keep the work done on a prefix and reuse it when a later request starts with exactly the same tokens. The moment two requests differ, caching stops for the rest of the prompt.
Two things follow from that, and both matter more than the discount itself.
Order decides everything. Stable content has to come first. If a request starts with something unique, like a timestamp or a user ID, nothing after it can be reused. Put the system prompt, instructions, examples and fixed context first, and the user's message last.
The match has to be exact. One changed character early in the prompt breaks the cache from that point on. Adding today's date to a system prompt, or shuffling the order of your examples, is enough to lose the discount even when 99% of the text is the same.
What caching costs, by provider (November 2026)
These come from each provider's published schedule, checked on 17 Nov 2026. Rates are multiples of the model's normal input price.
| Provider | Cache read | Cache write | How it's turned on |
|---|---|---|---|
| OpenAI, GPT-5.6 and later | 0.1× (0.05× on GPT-6.1 Sol and Terra) | 1.25× for the default 30-minute cache, 2.5× for the 12-hour option | Automatic on prompts of 1,024 tokens or more |
| OpenAI, GPT-5.5 and earlier | Discounted | No write fee | Automatic |
| Anthropic (Claude) | 0.1× (0.05× on Sonnet 5.5 and Opus 5.5) | 1.25× for a 5-minute cache, 2× for a 1-hour cache | You mark the prefix with cache_control, or turn on automatic caching |
| Google (Gemini), implicit | 0.1× | None listed | Automatic above a minimum length (4,096 tokens on the current Flash models) |
| Google (Gemini), explicit | 0.1× | Storage, billed per million tokens per hour | You create a cache and choose how long it lives |
Three things in that table change the decision.
OpenAI's caching is no longer free on new models. On GPT-5.6 and later, a cache write costs 1.25× the normal input rate, the same premium Anthropic charges. A lot of older advice, including the first version of this post, said OpenAI caching costs nothing to turn on. That's still true for GPT-5.5 and earlier, but not for the models most people are moving to.
Anthropic refreshes its cache for free on every hit. The 5-minute timer restarts each time a cached prefix is read. A feature with steady traffic writes the cache once and then reads it all day.
Google's explicit caching charges for storage. You pay per million cached tokens per hour, whether or not anything reads them. On Gemini 3.6 Flash that's $0.50 per million tokens per hour until 31 December 2026, rising to $1.00 from 1 January 2027, when the model's token rates also double. Implicit caching has no storage fee and no setup.
What it saves on a real workload
Take a support assistant on Claude Sonnet 5. Its published rates are $2 per million input tokens, $2.50 for a 5-minute cache write and $0.20 for a cache read. Every request starts with the same 5,000-token system prompt, and the feature handles 50,000 requests a day.
- Without caching, the prefix alone is 250 million input tokens a day: 250 × $2 = $500 a day.
- With caching and steady traffic, the prefix is written once and read 49,999 times: 250 million × $0.20 per million ≈ $50 a day, plus a cent or so for the write.
That's about $450 a day, or roughly $13,500 a month, from one change, before counting the user messages on top, which cost the same either way.
The same feature on OpenAI's GPT-6 Luna ($0.10 input, $0.01 cached read, $0.125 cache write) goes from $25 a day to about $2.50. The percentage is the same. The dollars depend on the model.
When caching costs you money
Caching is a bet that a prefix will be read again before it expires. Three patterns lose that bet.
Prompts that are different from the first token. No shared prefix, nothing to reuse. Putting variable data near the top of the prompt does the same thing by accident.
Writes that are never read. On Anthropic, and on OpenAI from GPT-5.6, every write costs 1.25× input. A prefix that changes on every request pays that premium every time and never collects the read discount, so caching makes the feature more expensive than leaving it off. I wrote up how to spot this from your usage data in when prompt caching makes your LLM bill bigger.
Gaps longer than the cache lives. OpenAI's default cache lasts at least 30 minutes, Anthropic's 5 minutes from the last hit. A feature with sparse traffic can arrive after the cache has expired every time. The longer options (OpenAI's 12-hour cache, Anthropic's 1-hour cache) fix that, at a higher write price: worth it only if they save more than one re-write in their lifetime.
How to know it's working
Your provider's dashboard shows one total for the month. It won't tell you which feature's cache broke last Tuesday. Every provider does return cache counts on each response, though, so you can check per feature:
// OpenAI Responses API
const { input_tokens, input_tokens_details } = response.usage;
const read = input_tokens_details.cached_tokens;
const written = input_tokens_details.cache_write_tokens ?? 0;
// Anthropic Messages API
const { cache_read_input_tokens, cache_creation_input_tokens } = message.usage;A healthy feature shows many reads for every write. Writes that keep pace with your request count mean the prefix is changing. Zero reads and zero writes means caching isn't on, or the prompt is under the minimum length.
Check again after every prompt change. Caches rarely break on the day you set them up. They break three weeks later, when someone adds the date to the system prompt.
Where LLMtrack fits
LLMtrack prices every request from the token counts your SDK call sends, with cache reads and cache writes as their own lines at their own rates, never blended into input. Its Cache Intelligence view shows the hit rate and the money saved for each feature, so a broken cache shows up on the feature it belongs to the same day.
llmtrack.track({
provider: 'anthropic',
model: message.model,
feature: 'support-assistant',
...fromAnthropicUsage(message.usage),
});It never sees your prompts, so it can tell you a cache broke and when, but not which line of the prompt did it. To estimate a feature before you change anything, the LLM cost calculator takes cached tokens as an input, and the LLM API pricing sheet lists read and write rates wherever a provider publishes them. You can start on the free plan, which includes Cache Intelligence.
Related: why your system prompt is your biggest cost driver and how conversation history inflates chat costs.
FAQ
A cached prefix bills at about 0.1× the normal input rate on OpenAI, Anthropic and Gemini, and 0.05× on a few of the newest models. On a feature where most of the prompt is fixed context and traffic is steady, that cuts input cost by close to 90%. Output tokens cost the same either way.
On GPT-5.5 and earlier, yes: there's no charge to write the cache. On GPT-5.6 and later, a cache write costs 1.25× the normal input rate for the default 30-minute cache, or 2.5× for the 12-hour option. Reads cost 0.1× input, or 0.05× on GPT-6.1 Sol and Terra.
Yes. A 5-minute cache write costs 1.25× the model's input rate and a 1-hour cache write costs 2×. Reads cost 0.1× input on most models and 0.05× on Sonnet 5.5 and Opus 5.5. The 5-minute timer resets for free each time the cache is read.
The usual causes are something that changes on every request near the start of the prompt, tool definitions that change between calls, traffic gaps longer than the cache lifetime, and prompts shorter than the model's minimum cacheable length. Compare cache reads and writes per feature to see which one it is.
Gemini has two modes. Implicit caching is automatic, discounts repeated prefixes to about 0.1× input and has no storage fee. Explicit caching lets you create a cache with a lifetime you choose and charges storage per million tokens per hour on top of the discounted reads.
Sources
Checked on 17 Nov 2026:
See what caching saves, per feature
Free plan, every feature, no card.
Start tracking free →