LLM Agent Cost Control: How One Bad Loop Can Cost You $200 in an Hour
An agent stuck in a loop keeps calling the model with a growing context until something stops it. What that costs per hour, the six limits that bound it, and where each one lives.
A normal request ends when the model answers. An agent run ends when the model decides it's done, and sometimes it doesn't decide. A tool keeps returning an error and the agent keeps retrying it. Two steps undo each other. A search never finds what the agent is looking for, so it searches again.
Each of those turns is a full model call carrying the whole run's context, which grows with every step. The loop doesn't crash or throw an error. It just keeps spending until something outside it stops it.
This post is part of the "Prevent cost surprises" section of the complete guide to LLM cost optimization.
What a loop costs
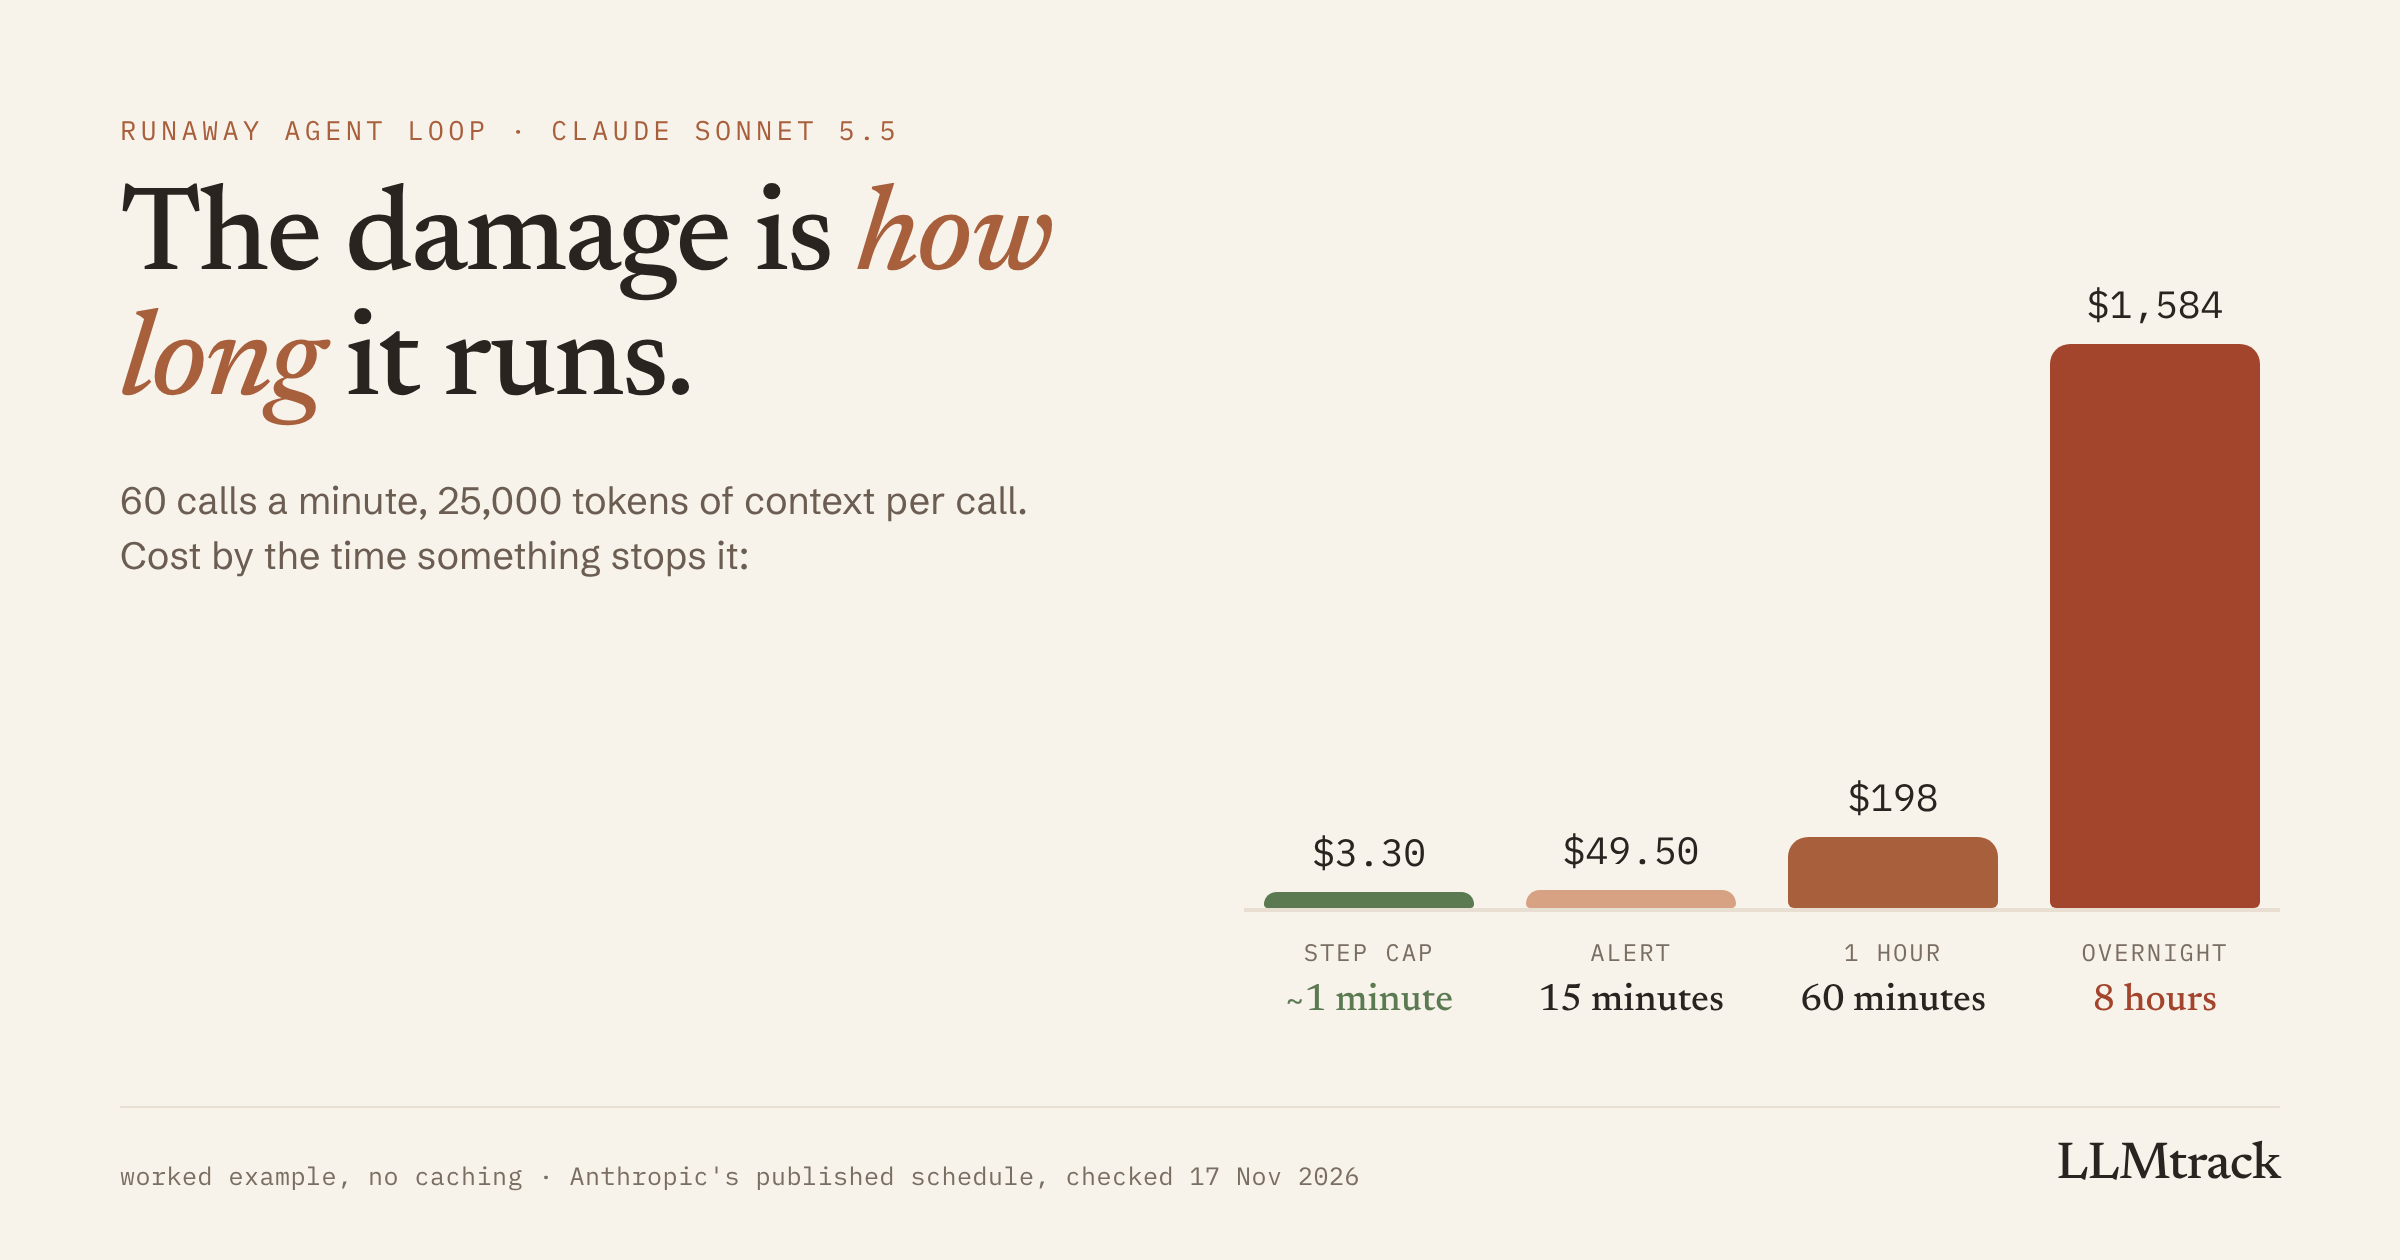
Take a few agent runs stuck at the same time, adding up to 60 calls a minute. By the time a run is stuck, its context has grown: say 25,000 input tokens and 500 output tokens per call. On Claude Sonnet 5.5 at its published rates on 17 Nov 2026 ($2 input, $10 output per million), each call costs $0.055:
| Stopped after | Cost |
|---|---|
| 1 minute | $3.30 |
| 15 minutes | $49.50 |
| 1 hour | $198 |
| 8 hours (overnight) | $1,584 |
| 7 days | $33,264 |
These are worked numbers, not an incident. Caching would lower them, since a loop resends the same context, but it doesn't stop the loop. Change the model, call rate and context size to see your own:
Runaway loop cost calculator
Enter what a stuck loop looks like for your agent. The table shows what it costs depending on how long it runs before something stops it. Rates in USD per million tokens, checked 17 Nov 2026, without caching.
The table makes the point: what decides the damage isn't the model or the prompt. It's how long the loop runs before something stops it.
Six limits that bound agent cost
1. A maximum number of steps per run. The single most effective limit. Look at how many steps successful runs take (the 99th percentile is a good start) and cap a little above that. The OpenAI Agents SDK takes max_turns and raises MaxTurnsExceeded when it's hit. The Claude Agent SDK takes maxTurns (max_turns in Python). In your own loop, it's a for loop with a limit instead of while (true).
2. A spend budget per run. Add up the cost of each call from its usage data as the run goes, and stop when it passes a limit. The Claude Agent SDK has this built in as maxBudgetUsd (max_budget_usd). Note that both of its caps are off unless you set them.
3. A wall-clock timeout. A run that's been going for 20 minutes when runs normally take two is stuck, whatever its step count.
4. Repeated-call detection. If the agent calls the same tool with the same arguments three times in a row, or a tool errors three times running, stop the run or hand it to a person. This catches the most common loop before the step cap does.
5. A provider spend limit as the backstop. OpenAI lets you set hard monthly limits per project, Anthropic per workspace, and Google AI Studio per project. Give agents their own project or workspace so a runaway agent hits its own limit instead of taking down every other feature. Cost alerts and budget limits covers each provider.
6. A spend-velocity alert. Alert when a feature's spend in the last hour is several times its normal rate. It catches what the limits above miss, like a bug that starts thousands of short runs instead of one long one.
Make the limits fail well
A run that hits a limit should end cleanly: save what it has done, tell the user it couldn't finish, and log why. If the response to a stopped run is an automatic retry, the cap just moves the loop up one level. Count retries of whole runs, and give them a limit too.
It also helps to know what normal looks like before setting limits. AI agent cost per run shows how to measure the median and 95th-percentile cost per run, which is what the caps should be set from.
Where LLMtrack fits
LLMtrack records each call's cost as it happens, with the feature, customer and any run ID you attach, so a stuck agent shows up as one run with an unusual number of steps and one feature with a sudden rise in spend. Email alerts on the Pro plan fire on spend thresholds. It can't stop a run, because it isn't in the request path, so the step cap and per-run budget belong in your agent code. You can start on the free plan.
import { fromAnthropicUsage } from 'llmtrack';
const MAX_STEPS = 25;
let runCost = 0;
for (let step = 1; step <= MAX_STEPS; step++) {
const response = await anthropic.messages.create({ model: 'claude-sonnet-5-5', max_tokens: 2048, tools, messages });
const u = response.usage;
runCost += (u.input_tokens * 2 + u.output_tokens * 10) / 1e6; // rough guard, uncached Sonnet 5.5 rates
llmtrack.track({
provider: 'anthropic',
model: response.model,
feature: 'support-agent',
metadata: { runId, step },
...fromAnthropicUsage(u),
});
if (runCost > 0.50) throw new Error('Run budget exceeded');
if (response.stop_reason !== 'tool_use') break;
messages.push({ role: 'assistant', content: response.content }, await runTools(response));
}FAQ
Set it from your own data: look at how many steps successful runs take and cap a little above the 99th percentile. For many tool-using agents that's somewhere between 10 and 30, but it depends entirely on the task.
Add up each call's cost from its usage data as the run goes, and stop when the total passes your limit. The Claude Agent SDK has a built-in maxBudgetUsd option; with other frameworks it's a few lines in the loop.
Whatever your code does. End the run cleanly, keep any partial results, tell the user, and log the reason. Avoid automatically retrying the whole run, or the limit just moves the loop.
They stop it eventually, but they apply to the whole project or workspace, so they also stop every other feature sharing it. Use them as a backstop, with step and spend limits inside the agent as the first line.
Because every step resends the full context of the run, which grows each step, and nothing outside the loop stops it by default. A stuck run keeps paying for its largest requests until a limit or a person ends it.
Sources
Checked on 17 Nov 2026:
Catch a stuck agent the same hour
Free plan, every feature, no card.
Start tracking free →