LLM Cost Alerts and Budget Limits: A Setup Guide
A runaway LLM process can spend a month of budget in an hour, and a provider dashboard won't say which feature did it. What to alert on, with example thresholds, where OpenAI and Anthropic let you set hard limits, and how to make an alert name the cause.
An LLM bill is one of the few costs that can multiply without a matching signal anywhere else. Traffic looks normal, latency looks normal, error rates look normal, and the day's spend is already five times the average because a retry loop is firing, an agent is stuck, or one integration started sending ten times its usual volume.
What makes it expensive is timing. Provider dashboards show totals by day, model and API key, but not by product feature, so even when a spike shows up, nobody can tell what caused it without digging. Alerting closes that gap: it turns a cost problem from something you find on the invoice into something you catch while it's happening.
This post is part of the "Prevent" section of the complete guide to LLM cost optimization.
Alert on the right signals, not just the total
A single monthly threshold is better than nothing, but it fires late and tells you nothing about the cause. A useful setup watches several things at once.
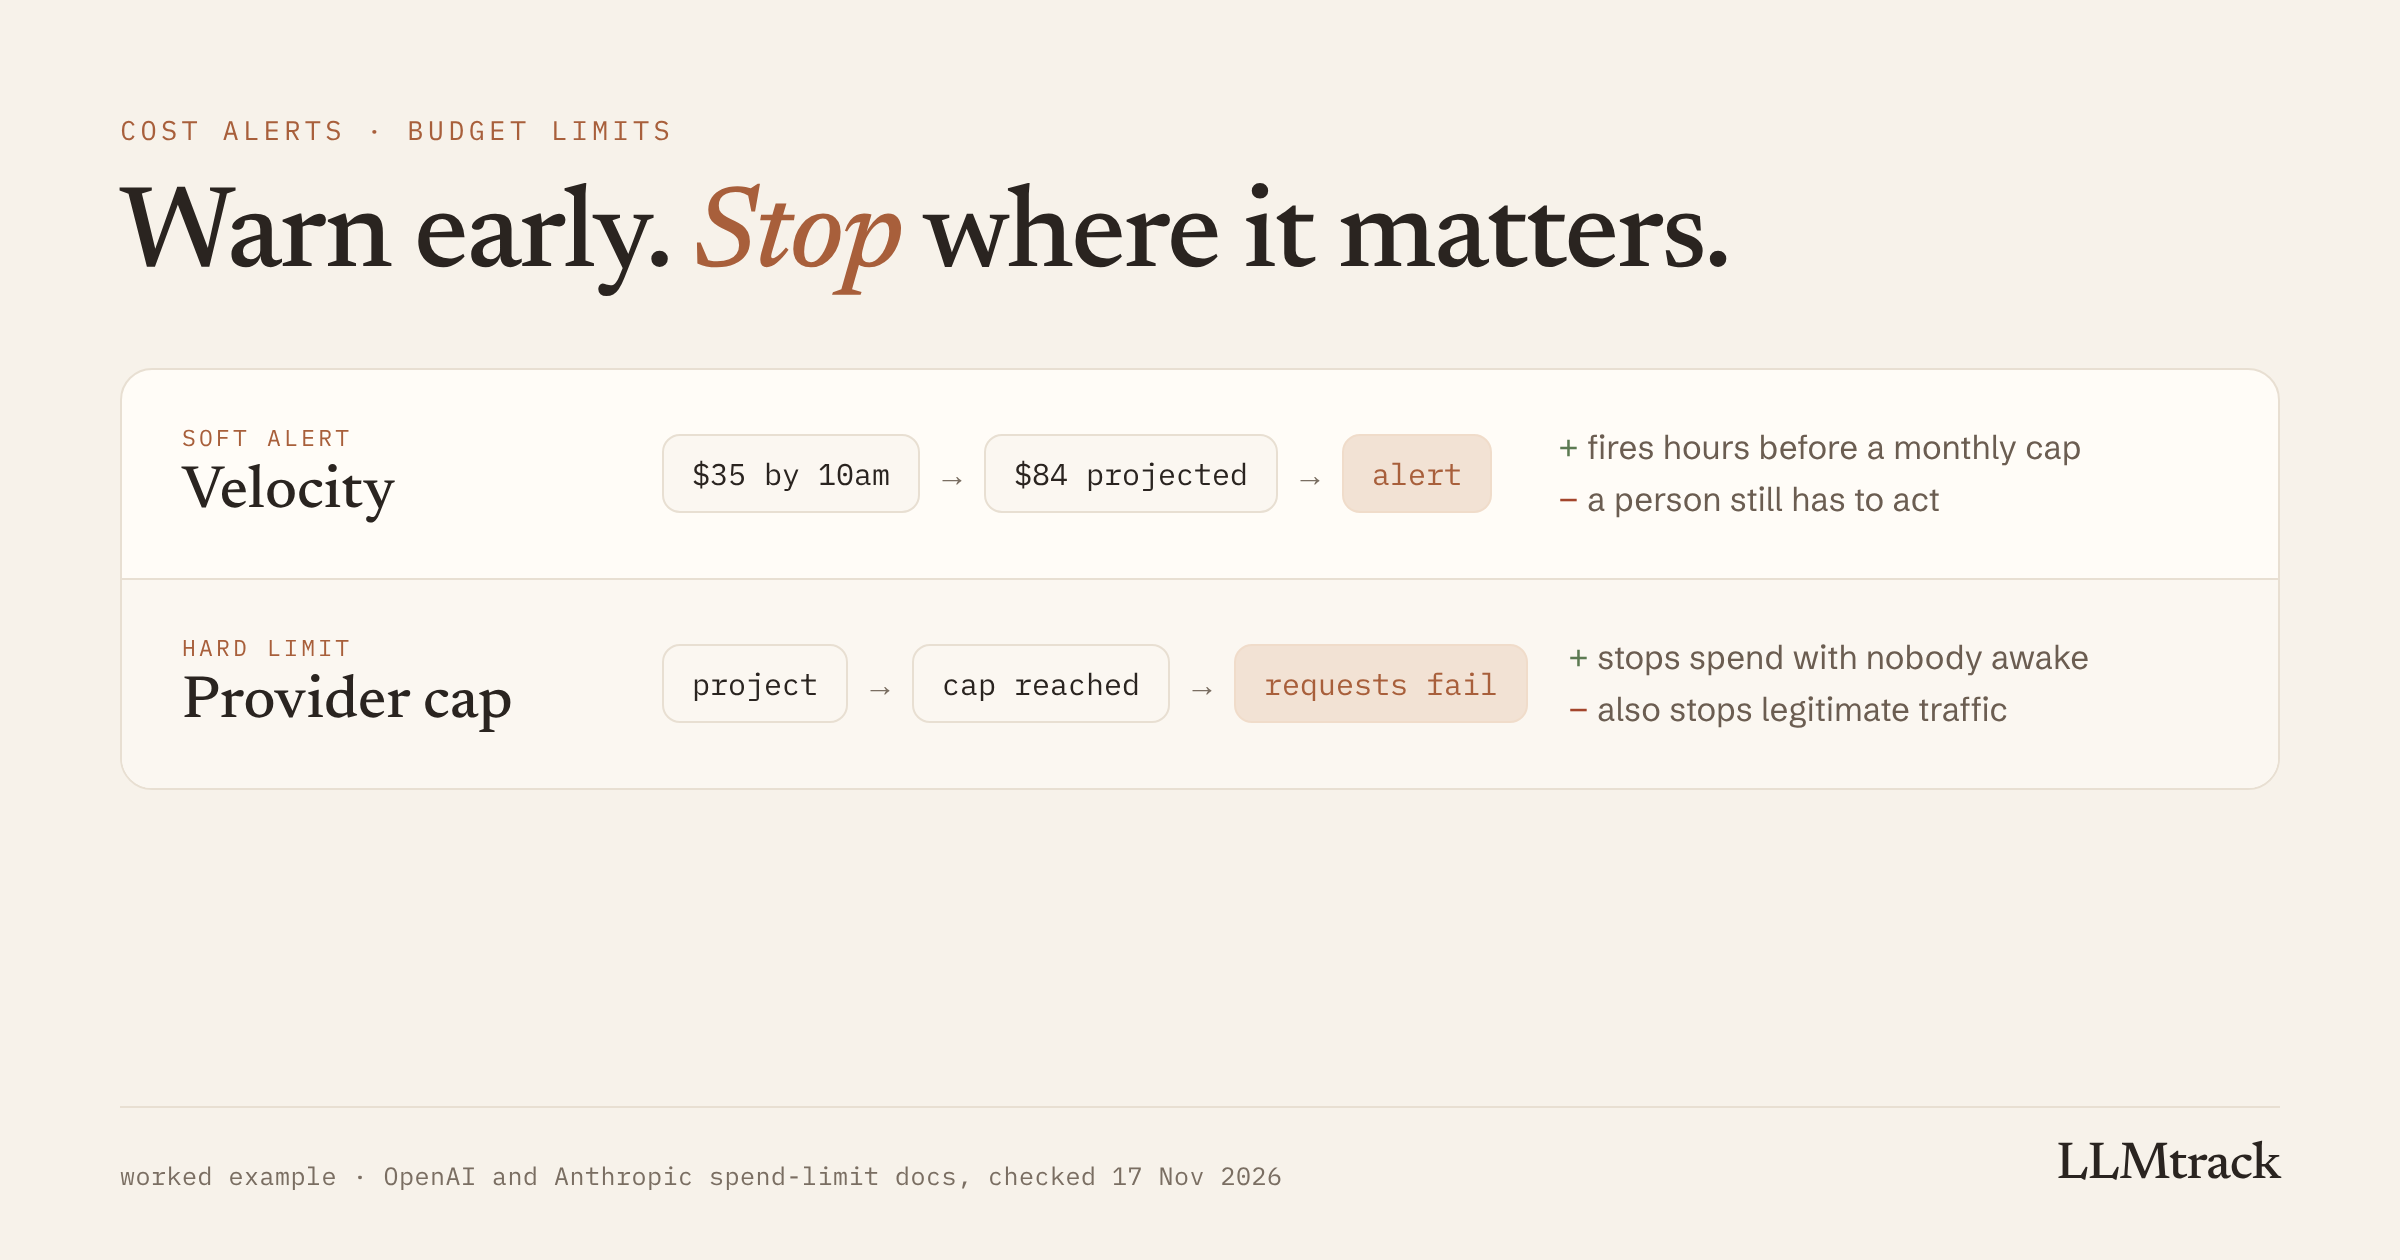
Spend velocity. The most valuable alert is usually a rate, not a total. Say a product averages $40 a day. An alert that fires when today's projected spend passes twice the trailing 7-day average catches a runaway process by mid-morning: if $35 is gone by 10am, the day is on course for about $84, and the alert fires while there's still most of the day left to save. A monthly ceiling wouldn't notice for another week.
Absolute thresholds. A daily and a monthly ceiling. The daily one catches acute incidents; the monthly one catches slow drift. Set the daily threshold from your real daily average, not a round number.
Per-feature spend. "Spend is high" sends you looking. "The summarizer is 80% of today's spend, up from 30%" sends you to the fix. That only works if every call carries the name of the feature that made it.
Per-customer spend. In a multi-tenant product, one customer can dominate the bill. A per-customer threshold names the account, which is both a cost signal and often a pricing or abuse signal. Which customer is costing you money covers what to do once you know.
Error-rate spikes. Failed calls often still cost money, and a surge in errors usually comes with a retry storm. An error-rate alert catches that class of incident earlier than a spend alert does. How retry logic inflates an LLM bill shows the pattern.
Soft alerts versus hard limits
These are two different tools.
A soft alert tells a person that something crossed a line. It's right when someone has to judge whether the spend is legitimate: a launch-day traffic surge and a runaway loop look the same on a spend chart, and only context tells them apart.
A hard limit stops spending automatically once a budget is hit. It's right for lines that should never be crossed regardless of context: a cap on an experimental feature, a key used by an untrusted integration, a development environment.
Use both. Soft alerts for the broad picture, hard limits on the specific keys and features where an automatic stop is safer than waiting for someone to read a message.
Where you can set a hard limit
Hard limits have to live somewhere that sees the request before it's sent, or at the provider:
- OpenAI lets you set hard monthly spend limits for an organization and, since 22 July 2026, for individual projects. Requests fail once a limit is reached until it's raised or the month resets.
- Anthropic applies a monthly spend cap per organization on its standard usage tiers, which you can set lower yourself, and each workspace can have its own monthly spend limit.
- A gateway or proxy in your request path can enforce budgets per key, user or team. LiteLLM's proxy, for example, has a
max_budgetper virtual key. Portkey vs LiteLLM vs OpenRouter compares the options.
One project or workspace per feature or team gives you the most precise provider-side limits. It also gives you per-team totals for free.
Make the alert land where someone will see it
An alert that fires into an unwatched inbox isn't an alert. Send cost alerts to whatever the team actually watches, and make each one readable at a glance:
- what crossed the line, and by how much
- which feature, key or customer is responsible
- the current run-rate and the projected total for the day or month
An alert that only says "spend is high" starts an investigation. One that names the cause starts a fix.
Forecast so the alert isn't the first warning
Alerts fire once a line is crossed. A forecast tells you before: projecting the month from recent daily spend turns "you're over budget" into "at the current rate you'll cross your budget on the 20th." When will your AI bill cross your budget works through the arithmetic, and how to know next month's AI bill today covers the longer view.
Forecasts also catch the changes that don't come from your traffic. Gemini Flash doubles in price on 1 January 2027; a feature that's fine in December will cost twice as much in January with no change in usage. What the Gemini Flash increase does to your bill has the numbers.
Putting it together
A complete setup has four parts: a velocity alert to catch incidents early, per-feature and per-customer thresholds so every alert names a cause, hard limits on the keys and features that should never run unbounded, and a forecast so the budget crossing is visible before it happens.
All four depend on the same thing: knowing what each request cost, with its feature and customer attached, as soon as it completes. That's what LLMtrack records. Each request is priced as it arrives, email alerts on the Pro plan fire on spend thresholds, and the Forecast page shows the day you'll cross your budget. It can't block a request, since it isn't in the request path, so pair it with provider spend limits for the hard stops. You can start on the free plan.
FAQ
Spend velocity (today's projected spend against the trailing average), per-feature spend, per-customer spend, and error-rate spikes. A single monthly total fires too late and doesn't tell you the cause.
Yes. OpenAI lets you set hard monthly spend limits for an organization and for individual projects. Once a limit is reached, requests fail until the limit is raised or the month resets.
Yes. Anthropic applies a monthly spend cap per organization on its standard tiers, which you can lower, and each workspace in the Claude Console can have its own monthly spend limit.
A common starting point is twice the trailing 7-day daily average, applied to today's projected spend. Tighten it once you know how spiky your normal traffic is.
Both. Soft alerts where a person needs to judge whether spend is legitimate, and hard limits on experimental features, untrusted integrations and development keys, where an automatic stop is safer.
Sources
Checked on 17 Nov 2026:
Get alerts that name the feature
Free plan, every feature, no card.
Start tracking free →