LLM Prices Keep Falling. Here's Why Your Bill Doesn't.
The price of a fixed level of LLM capability falls by roughly 10× a year or more, by a16z's and Epoch AI's measures. Bills still rise, because teams move to newer models, use more tokens per task and run more tasks. The arithmetic, current examples, and what to watch.
In November 2024, a16z gave the trend a name: LLMflation. Its measure was the cost of a model at a fixed level of capability, and it found that cost falling by about ten times a year. Epoch AI's measurements since point the same way, at rates from 9× to 900× a year depending on the benchmark.
And yet very few teams have watched their LLM bill fall by ten times a year. Most have watched it grow. Both things are true, and the reason matters for anyone budgeting AI features.
This post is part of the "Understand what drives your bill" section of the complete guide to LLM cost optimization.
What the price trend actually measures
a16z's analysis tracked the cheapest model reaching a given benchmark score over time. For a model of equivalent performance, it found the cost decreasing by about 10× every year.
Epoch AI did a similar analysis across several benchmarks and performance levels. It found declines ranging from 9× to 900× a year, depending on the milestone; reaching GPT-4's performance on a set of PhD-level science questions, for example, got 40× cheaper a year. A 2025 academic paper, "The Price of Progress", estimated 5× to 10× a year for frontier models on knowledge, reasoning, maths and software engineering benchmarks.
The key words in all three are a given level of performance. They measure what it costs to buy yesterday's capability today. That's not what most products buy.
Why the bill goes the other way
You move to newer models. When a better model comes out, most teams switch, because users notice. The newest models carry the newest prices, and a flagship's list price falls much more slowly than the price of last year's capability.
Tokens per task grow. Reasoning models think before answering, and the thinking is billed at the output rate. Agents make several calls per task, each resending a growing context. A task that was one call two years ago can be ten today. AI agent cost per run shows how fast that compounds.
Tasks grow. Cheaper tokens make new features viable, and features that work get used more. That's the point of building them, but it lands on the bill.
Some prices go up. Google launched Gemini 3.6, 3.7 and 3.8 Flash at introductory rates that double on 1 January 2027, and set Gemini 4 Argon and Carbon to double on 1 December. The Gemini Flash increase has the numbers.
The arithmetic
Your bill changes each year by:
volume growth × tokens-per-task growth ÷ price-per-token decline
If tasks grow 2.5× in a year and tokens per task 1.5×, prices have to fall 3.75× just for the bill to stay flat. If you stay on the same model and its price doesn't change, the bill grows 3.75×.
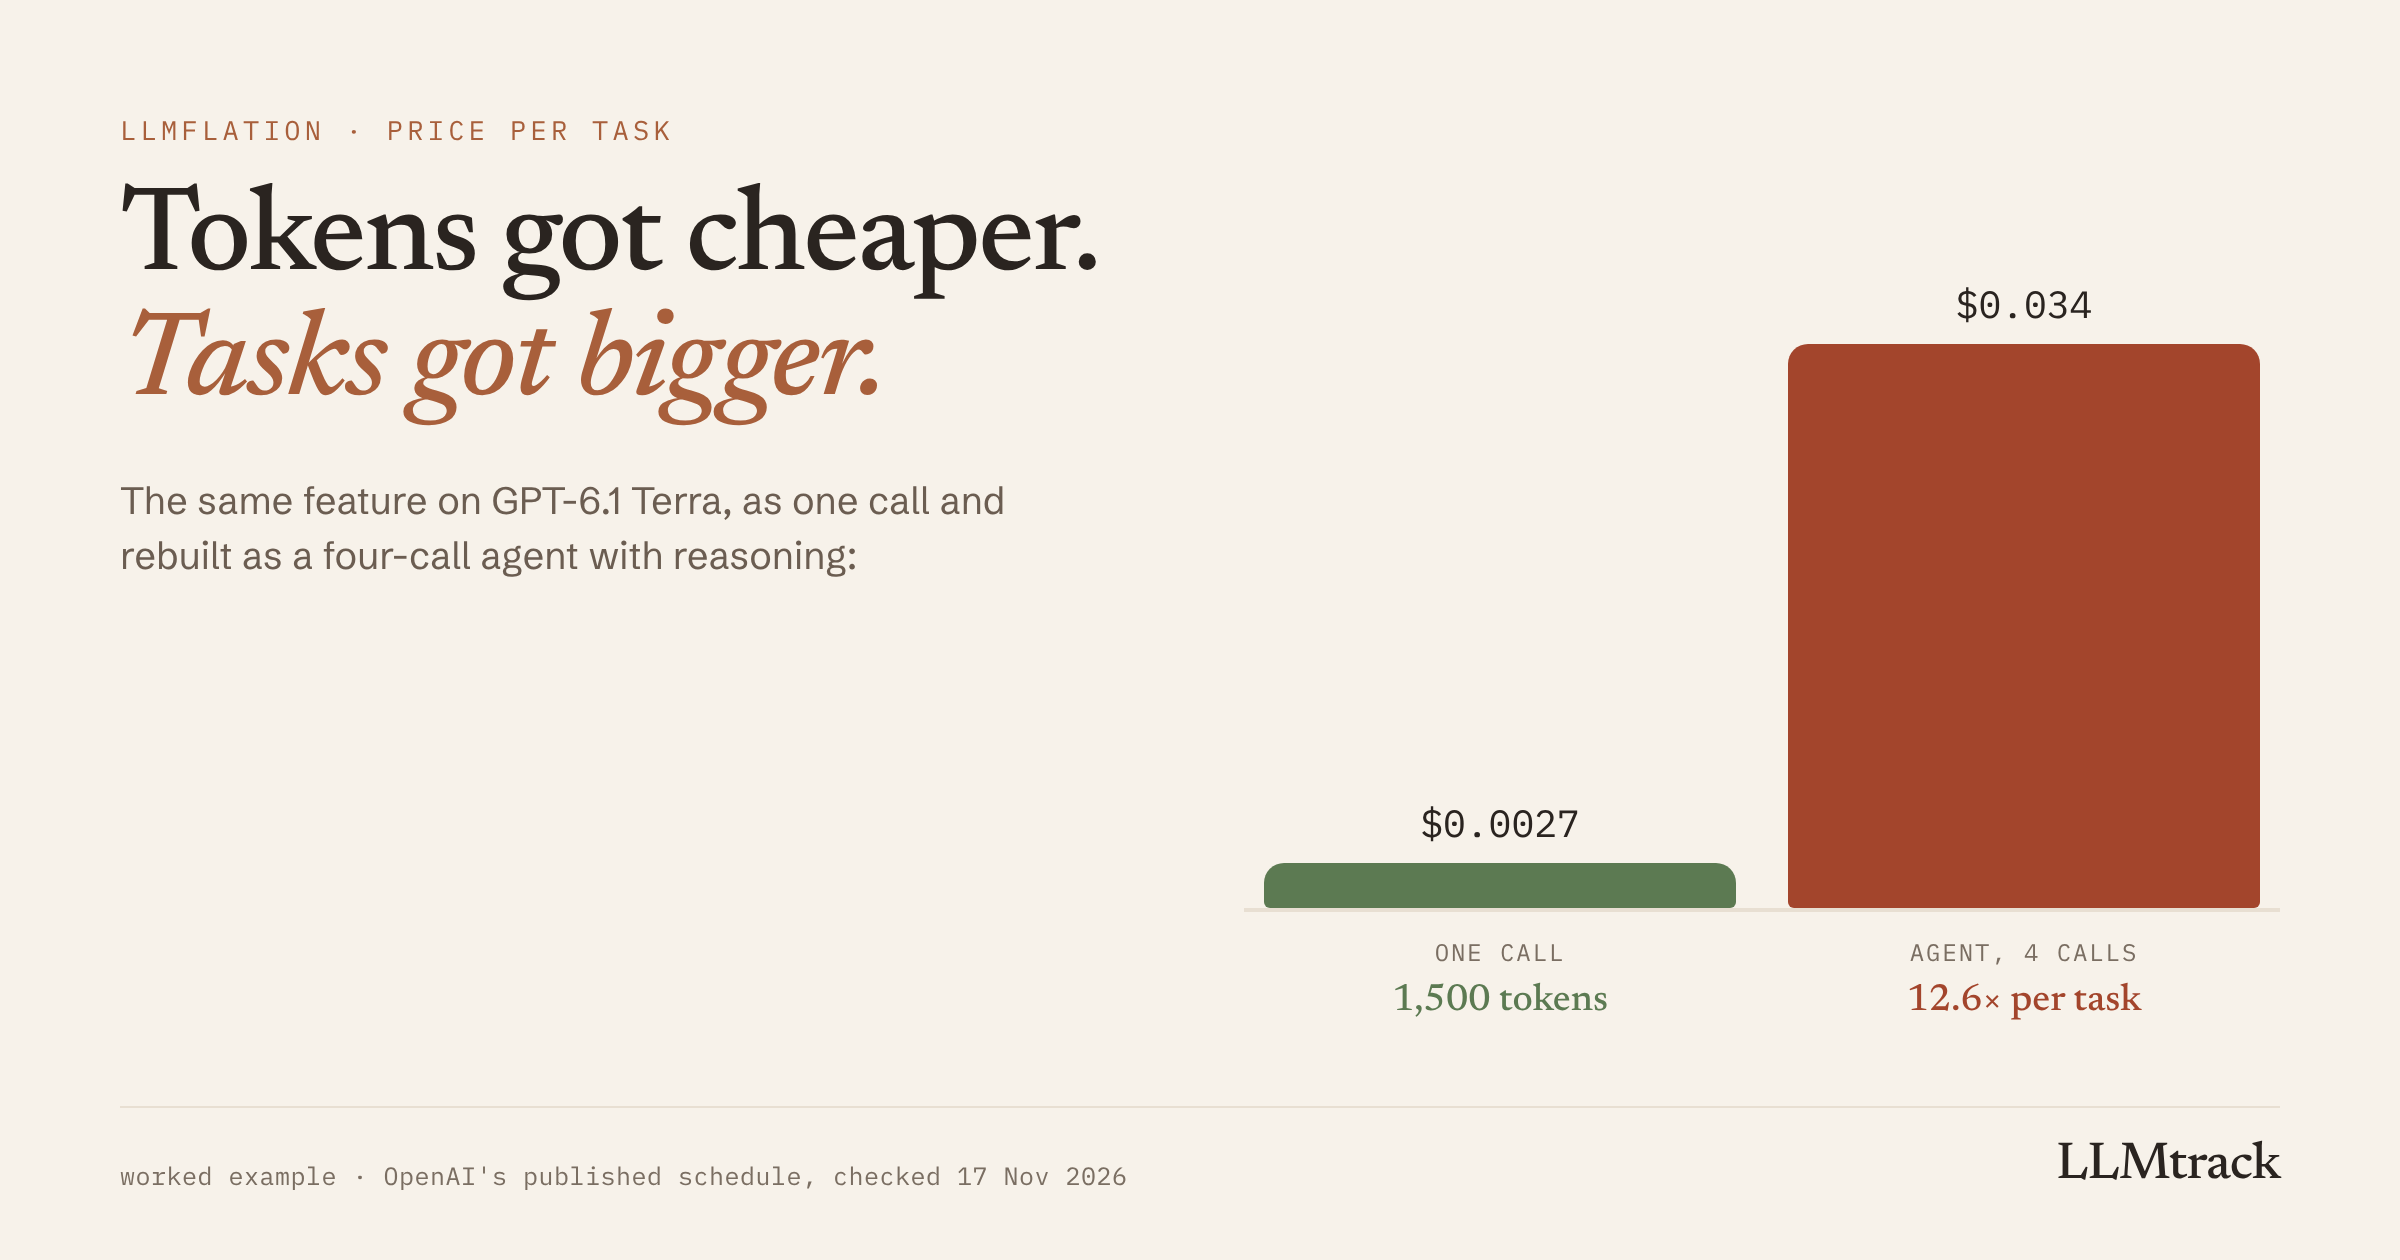
A concrete example at today's rates, on GPT-6.1 Terra ($1 input and $5 output per million tokens, OpenAI's published schedule on 17 Nov 2026). A feature that answers with one call of 1,200 input and 300 output tokens costs $0.0027 per task. Rebuild it as an agent that makes four calls averaging 3,000 input, 300 output and 800 reasoning tokens, and it costs $0.034 per task, 12.6× more. A 10× fall in price per token wouldn't cover that.
Price drop vs usage growth
Enter your monthly bill today and three yearly rates. The bill each year is today's bill × (volume growth × tokens-per-task growth ÷ price decline). An illustration, not a forecast: price declines only reach you if you move to cheaper models.
What to do about it
Track cost per task, not price per token. The provider's price chart tells you nothing about your bill. Cost per task for each feature, over time, tells you whether you're getting cheaper or more expensive.
Re-test older, cheaper models. If a task hasn't changed, the model that does it well enough has probably got cheaper, or a smaller one has caught up. Should you switch to a cheaper model covers the test.
Watch tokens per task. Reasoning effort, agent steps, retrieved context and conversation history all grow quietly. How to reduce output tokens covers the biggest lever.
Forecast with your own growth rate. Your own trend in tasks and tokens per task tells you next quarter's bill; the industry price trend doesn't. How to know next month's AI bill today covers the method.
Seeing your own trend
LLMtrack records each request with its feature and model, priced at the rate in force when it was made, so you can see cost per request and per feature over time, and tell volume growth from price changes. Its forecast projects the month from your own daily spend. You can start on the free plan.
import { fromOpenAIUsage } from 'llmtrack';
llmtrack.track({
provider: 'openai',
model: res.model,
feature: 'research-agent',
metadata: { taskId, step },
...fromOpenAIUsage(res.usage),
});FAQ
A term from a 2024 a16z analysis for the rapid fall in LLM inference cost: for a model of equivalent performance, about 10× cheaper every year.
Because you're probably not buying a fixed level of capability. Newer models cost more than last year's capability does today, reasoning and agents use more tokens per task, and usage grows. The bill rises whenever those outpace the price fall.
The trend for a fixed level of capability has held for several years, and a16z noted at the time that the rate may slow. Individual models can still get more expensive, as Gemini Flash does on 1 January 2027.
Track cost per task for each feature over time. If it falls while quality holds, you're getting more efficient. If total spend rises only because tasks grew, that's growth, not inefficiency.
Tokens per task and tasks per day, per feature. Either one growing faster than you expected shows up there weeks before it shows up on the invoice.
Sources
Checked on 17 Nov 2026:
Track cost per task, not price per token
Free plan, every feature, no card.
Start tracking free →